# Rocket Job - Complete Documentation
> Rocket Job is a distributed, priority-based background job and batch processing system for Ruby, backed by MongoDB.
This file concatenates every page of https://rocketjob.reidmorrison.com for consumption by AI assistants.
It is generated from the markdown sources in docs/ by `bundle exec rake llms_full`; do not edit it directly.
A per-page index is available at https://rocketjob.reidmorrison.com/llms.txt
---
## What is Rocket Job?
Rocket Job is a distributed, priority-based background job and batch processing system for Ruby.
It is built to do two things that ordinary background job frameworks struggle with:
1. **Run conventional background jobs reliably, in business priority order.** A job is a real
Ruby class with typed, validated fields. It is persisted to MongoDB, picked up by any
available worker, and processed in priority order so that business-critical work jumps ahead
of routine work. Every job is tracked from the moment it is queued until it completes, fails,
or is aborted.
2. **Process a single huge workload across thousands of workers at once.** Add one line,
`include RocketJob::Batch`, and a job's input is uploaded into MongoDB, split into small
*slices*, and processed concurrently across every available worker. A file with millions of
rows becomes thousands of bite-size slices that run in parallel and can be paused, resumed,
retried, or aborted as a whole.
The same framework covers both the small recurring job and the multi-gigabyte file import, with
one programming model and one place to watch it all run.
## Why use it?
### The problem with ordinary background jobs
Most Ruby background job frameworks were designed for one thing: run a short method, soon, on one
worker. That works until your needs grow past it:
* You need to process a file with ten million rows. One worker grinding through it for hours is
not an option, and Redis-backed queues cannot spill that much data to disk.
* You need business-critical work to preempt routine work, not just sit in the same FIFO queue.
* You pass arguments as an untyped array or hash, with no validation, so a malformed job is only
discovered when it blows up mid-run.
* When a job fails at row 4,000,000, you want to retry just the failed slice, not start over.
* You want to *see* what is queued, running, and failed, and change a job's priority or retry it,
without shelling into a console.
### Is Rocket Job the right fit?
If you need conventional background jobs (send an email, update a record) and nothing more, a
Redis-backed queue like Sidekiq or a database-backed one like Solid Queue will be simpler to
operate, and your Rails app may already include one.
Rocket Job is worth adding when your work outgrows that model:
* You process files with millions of records and want them handled in parallel across many workers,
not ground through one at a time.
* You need jobs to run in strict business-priority order, with critical work preempting routine
work.
* You want to retry a single failed slice of a large job rather than restarting the whole thing.
It is built for the large-batch, high-priority end of the spectrum, and it runs ordinary jobs
perfectly well too.
### The Rocket Job way
A job is an ordinary class with real fields:
~~~ruby
class ImportJob < RocketJob::Job
field :file_name, type: String
validates_presence_of :file_name
def perform
# Import the file ...
end
end
~~~
~~~ruby
ImportJob.create!(file_name: "users.csv", priority: 5)
~~~
That single `create!` validates the fields, persists the job to MongoDB, and queues it. Any worker
on any server can pick it up. Because `priority: 5` is well above the default of 50, it jumps ahead
of routine work.
To turn the very same job into one that processes a large file across every available worker, you
add one module and accept a record per call:
~~~ruby
class ImportJob < RocketJob::Job
include RocketJob::Batch
def perform(row)
# Called once per row, spread across all workers
User.create!(row)
end
end
~~~
~~~ruby
job = ImportJob.new
job.upload("users.csv")
job.save!
~~~
The file is uploaded into MongoDB, sliced, and processed in parallel. Nothing else in the job
changed.
### See everything running
Rocket Job ships with a web interface,
[Rocket Job Mission Control](mission_control.html), so queued, running, scheduled, completed, and
failed jobs are all visible, and you can change priority, retry, pause, or abort them from the
browser.
Scheduled jobs replace cron, with full visibility into what is scheduled and when it last ran:
### Reasons developers choose Rocket Job
* **Scales from one worker to thousands.** Batch jobs split work into slices that thousands of
workers, often across hundreds of containers, claim and process concurrently. See
[how it works](#how-it-works).
* **Priority based.** Jobs run in business priority order (1 is highest, 50 the default), and a
high-priority job will interrupt a running batch job to get resources, then let it resume.
* **Built for very large files.** Input is uploaded into MongoDB, which spills from memory to disk,
so files far larger than RAM are processed without a separate data store. Built-in support for
Zip, GZip, encrypted, delimited, and fixed-length files.
* **Typed, validated jobs.** Fields have real types and validations instead of an untyped argument
hash, so a bad job is rejected at `create!` time, not mid-run.
* **Reliable and resumable.** Every job and every slice is tracked. Failed slices keep their
exception and can be retried on their own; whole jobs can be paused, resumed, or aborted.
* **Compressed by default, encrypted when you need it.** Batch data is compressed in MongoDB out of
the box, cutting storage and network bandwidth. Encryption is opt-in and configured per job: turn
on encryption at rest for a job's slices with
[Symmetric Encryption](https://encryption.reidmorrison.com), or encrypt
individual fields on any job (batch or not) with `field :ssn, type: String, encrypted: true`, to
meet compliance requirements for sensitive data, with no change to your `#perform` code.
* **A familiar, ActiveRecord-like API.** `create!`, `field`, `validates`, queries, and callbacks
all feel like Rails models, because jobs are Mongoid documents.
* **Cron without a cron server.** Schedule recurring jobs with a `cron_schedule`; there is no
central scheduler to keep alive and no missed runs when one box is down.
* **Visible in production.** The web interface, plus high-performance structured logging via
[Semantic Logger](https://logger.reidmorrison.com), make it easy to operate.
## Quick start
Rocket Job runs with or without Rails. This is the shortest path to a running job. The
[Installation guide](installation.html) covers Rails, standalone, and the web interface in full.
### 1. Start MongoDB
Rocket Job stores all job data in [MongoDB](https://mongodb.com). The easiest way to run it locally
is Docker:
~~~bash
docker run --name rocketjob_mongo -p 27017:27017 -d mongo:6.0
~~~
### 2. Install the gem
~~~ruby
# Gemfile
gem "rocketjob"
~~~
~~~bash
bundle install
~~~
### 3. Configure MongoDB
Rocket Job needs two MongoDB clients: `rocketjob` for the jobs themselves and `rocketjob_slices`
for batch slice data. In a standalone setup, create `config/mongoid.yml`:
~~~yaml
development:
clients:
default: &default_development
uri: mongodb://127.0.0.1:27017/rocketjob_development
rocketjob:
<<: *default_development
rocketjob_slices:
<<: *default_development
~~~
See the [Installation guide](installation.html) for the full production-ready configuration.
### 4. Write a job
Create `jobs/hello_world_job.rb`:
~~~ruby
class HelloWorldJob < RocketJob::Job
def perform
puts "Hello World"
end
end
~~~
### 5. Start a worker
~~~bash
bundle exec rocketjob
~~~
### 6. Queue the job
From a console (`bundle exec irb`):
~~~ruby
require "rocketjob"
RocketJob::Config.load!("development", "config/mongoid.yml")
require_relative "jobs/hello_world_job"
HelloWorldJob.create!
~~~
The worker process picks up the job and logs something like:
~~~
I [job:5731...] HelloWorldJob -- Start #perform
Hello World
I [job:5731...] (0.120ms) HelloWorldJob -- Completed #perform
~~~
That is the whole loop: define a job, start a worker, queue the job. The
[Programmer's Guide](guide.html) covers the full API.
## A tour of the features
### Add typed fields
Give a job real, typed input. Fields are validated and persisted like ActiveRecord attributes.
~~~ruby
class ReportJob < RocketJob::Job
field :username, type: String
field :start_date, type: Date, default: -> { Date.today }
validates_presence_of :username
def perform
logger.info "Building report for #{username} from #{start_date}"
end
end
~~~
~~~ruby
ReportJob.create!(username: "jbloggs")
~~~
### Encrypt a sensitive field
Any field on any job can be encrypted at rest by adding `encrypted: true`. The value is transparently
encrypted with [Symmetric Encryption](https://encryption.reidmorrison.com) before it
is written to MongoDB and decrypted when you read it back, so your code just uses `job.ssn` as usual:
~~~ruby
class ReportJob < RocketJob::Job
field :username, type: String
field :ssn, type: String, encrypted: true
def perform
logger.info "Building report for #{username}" # ssn is never logged in the clear
end
end
~~~
~~~ruby
job = ReportJob.create!(username: "jbloggs", ssn: "123-45-6789")
job.ssn # => "123-45-6789" (decrypted), but stored encrypted in MongoDB
~~~
### Set business priority
Lower numbers run first. The default is 50; this one jumps the queue:
~~~ruby
ReportJob.create!(username: "jbloggs", priority: 5)
~~~
### Delay until later
~~~ruby
ReportJob.create!(username: "jbloggs", run_at: 2.hours.from_now)
~~~
### Run on a schedule (cron replacement)
Mix in the `Cron` plugin and set a schedule. When the job completes it automatically re-schedules
its next run, with no separate cron daemon to keep alive.
~~~ruby
class NightlyReportJob < RocketJob::Job
include RocketJob::Plugins::Cron
# Run at 1am UTC every day
self.cron_schedule = "0 1 * * * UTC"
def perform
# ...
end
end
~~~
~~~ruby
NightlyReportJob.create!
~~~
### Hook into the lifecycle with callbacks
~~~ruby
class ImportJob < RocketJob::Job
after_start :notify_started
def perform
# ...
end
def notify_started
ImportMailer.started(self).deliver_now
end
end
~~~
### Process a large file as a batch job
This is what sets Rocket Job apart. Include `RocketJob::Batch`, write a `perform` that handles a
single record, and upload a file. Rocket Job slices the file and runs the slices across every
available worker in parallel.
~~~ruby
class ReverseJob < RocketJob::Job
include RocketJob::Batch
# Keep the job after it finishes so the output can be downloaded
self.destroy_on_complete = false
# 100 lines per slice (the default)
input_category slice_size: 100
# Collect the return value of every perform call as output
output_category
def perform(line)
line.reverse
end
end
~~~
Upload a file and queue it. The file can be plain text, GZip, Zip, or encrypted; Rocket Job
detects and decompresses it before slicing:
~~~ruby
job = ReverseJob.new
job.upload("input.txt")
job.save!
~~~
Once it completes, download the combined output, optionally compressed on the way out:
~~~ruby
job.download("reversed.txt.gz")
~~~
Because the work is sliced, a single job can be paused, resumed, or aborted, and if any slices
failed you retry just those by retrying the job. The [Batch Guide](batch.html) covers multiple
output files, tabular (CSV/JSON/etc.) parsing, throttling, and error handling.
### Trigger jobs when files arrive
The built-in directory monitor, [Dirmon](dirmon.html), watches directories and automatically
queues a job for each new file that appears, so an upload can kick off a batch import with no glue
code.
## How it works
A Rocket Job server process (started with `bundle exec rocketjob`) registers itself in MongoDB and
runs a pool of worker threads. Each worker repeatedly asks MongoDB for the highest-priority job
that is ready to run, using an atomic `find_and_modify` so that thousands of workers across many
servers can claim work without ever colliding or running the same job twice. There is no separate
message broker: MongoDB is both the queue and the system of record.
For a **simple job**, one worker claims the whole job, runs `perform`, and records the result. Many
workers share the same queue, so each job is picked up by whichever worker is free next:
~~~mermaid
flowchart LR
j1["job"] --> queue[("MongoDB queue
(priority order)")]
j2["job"] --> queue
j3["job"] --> queue
queue -- find_and_modify --> worker1["worker"]
queue -- find_and_modify --> worker2["worker"]
queue -- find_and_modify --> workerN["worker"]
~~~
For a **batch job**, the input you upload is stored in a dedicated MongoDB collection and divided
into slices. Each slice is an independent unit of work that any worker can claim:
~~~mermaid
flowchart LR
input["input file"] --> slices["slices"]
slices --> worker1["worker"]
slices --> worker2["worker"]
slices --> worker3["worker"]
slices --> workerN["worker"]
worker1 -- slice 1 --> output["output collection"]
worker2 -- slice 2 --> output
worker3 -- slice 3 --> output
workerN -- slice N --> output
output --> download["download"]
~~~
This is why Rocket Job scales the way it does: adding workers (more threads, more servers, more
containers) simply means more slices are processed at once. MongoDB's ability to spill from memory
to disk is what lets a single job hold millions of records of input and output without exhausting
memory or needing a separate data store. A slice carries its own state, so a failure is isolated to
that slice, retains the exception that caused it, and can be retried on its own.
Because everything lives in MongoDB, the [web interface](mission_control.html) can show the live
state of every job and slice, and operators can re-prioritize, retry, pause, or abort work while it
runs.
## Compatibility
Rocket Job is tested against a matrix of Ruby, Mongoid, and Rails versions:
* **Ruby:** MRI 3.2, 3.4, and 4.0 are exercised in CI; JRuby 9.4 or newer is also supported. The
authoritative list is the [CI matrix](https://github.com/reidmorrison/rocketjob/blob/main/.github/workflows/ci.yml).
* **Mongoid:** 8.1, 9.0, and 9.1, as defined in
[Appraisals](https://github.com/reidmorrison/rocketjob/blob/main/Appraisals).
* **Rails / Active Record:** 7.2, 8.0, and 8.1, each paired with the Mongoid versions above (also
in `Appraisals`). Rails is optional; Rocket Job runs equally well standalone.
* **MongoDB server:** whatever your Mongoid version supports. Mongoid 8.1 through 9.1 currently
support MongoDB server 3.6 through 8.x; see the
[Mongoid compatibility matrix](https://www.mongodb.com/docs/mongoid/current/compatibility/).
These are the combinations run in CI. See
[ci.yml](https://github.com/reidmorrison/rocketjob/blob/main/.github/workflows/ci.yml) and
[Appraisals](https://github.com/reidmorrison/rocketjob/blob/main/Appraisals) for the current,
authoritative list.
## Next steps
* [Installation](installation.html): Rails, standalone, and the web interface.
* [Programmer's Guide](guide.html): the full job API, fields, scheduling, throttling, and callbacks.
* [Batch Guide](batch.html): large files, tabular data, and parallel processing in depth.
* [Mission Control](mission_control.html): the web interface.
* [Dirmon](dirmon.html): trigger jobs from arriving files.
---
## Installation
Rocket Job runs with or without Rails. This guide covers both, plus the optional web interface,
[Rocket Job Mission Control](mission_control.html).
## Compatibility
Rocket Job is tested against a matrix of Ruby, Mongoid, and Rails versions. The combinations
exercised in CI are the authoritative list; see
[ci.yml](https://github.com/reidmorrison/rocketjob/blob/main/.github/workflows/ci.yml) and
[Appraisals](https://github.com/reidmorrison/rocketjob/blob/main/Appraisals).
* **Ruby:** MRI 3.2, 3.4, and 4.0. JRuby 9.4 or newer is also supported.
* **Mongoid:** 8.1, 9.0, and 9.1.
* **Rails / Active Record:** 7.2, 8.0, and 8.1 (optional; Rocket Job also runs standalone).
* **MongoDB server:** whatever your Mongoid version supports. Mongoid 8.1 through 9.1 currently
support MongoDB server 3.6 through 8.x. See the
[Mongoid compatibility matrix](https://www.mongodb.com/docs/mongoid/current/compatibility/).
### AWS DocumentDB
Rocket Job's cross-process event mechanism (used for shutdown, pause, and log-level changes)
defaults to a *tailable capped collection*, which [Amazon DocumentDB](https://aws.amazon.com/documentdb/)
does not support. To run on DocumentDB, switch the event listener to the polling strategy, which uses
a regular collection instead. Add this to an initializer (for example
`config/initializers/rocketjob.rb`):
~~~ruby
RocketJob::Event.listener_strategy = :polling
~~~
With polling enabled, control events are delivered within `RocketJob::Event.poll_interval` seconds
(default `1`). Events are stored in a regular collection bounded by a TTL index;
`RocketJob::Event.event_retention_seconds` (default one hour) controls how long an event is kept,
which is also the longest a server can be offline and still recover events on restart. On a real
MongoDB server the default capped-collection strategy remains the lowest-latency choice and needs no
configuration.
#### Event listener settings
All of the event listener settings, with their defaults:
| Setting | Default | Applies to | Description |
|---------|---------|-----------|-------------|
| `RocketJob::Event.listener_strategy` | `:capped` | both | `:capped` tails a capped collection (lowest latency, requires capped-collection support); `:polling` polls a regular collection (works on any MongoDB-compatible store, including DocumentDB). |
| `RocketJob::Event.long_poll_seconds` | `300` | `:capped` | How long the tailable cursor waits for new events before re-issuing. |
| `RocketJob::Event.capped_collection_size` | `134217728` (128 MB) | `:capped` | Size of the capped collection, used only when it is first created. |
| `RocketJob::Event.poll_interval` | `1` | `:polling` | Seconds between polls. Bounds control-event delivery latency. |
| `RocketJob::Event.event_retention_seconds` | `3600` (1 hour) | `:polling` | TTL on stored events. Also the longest a server can be offline and still recover events on restart. |
## Licensing
A frequent objection to adopting Rocket Job is MongoDB's
[Server Side Public License](https://www.mongodb.com/legal/licensing/server-side-public-license)
(SSPL), which is not OSI-approved. It is worth being precise about what it does and does not require,
because the concern is usually broader than the license actually is.
* **Rocket Job and its client stack are permissively licensed.** Rocket Job is Apache 2.0. The gems
it uses to talk to the database, the [`mongo`](https://github.com/mongodb/mongo-ruby-driver) driver
and [`mongoid`](https://github.com/mongodb/mongoid), are Apache 2.0 as well. Nothing in the
Rocket Job stack is SSPL.
* **The SSPL covers the MongoDB server, and its copyleft only triggers on offering MongoDB itself as
a service to third parties.** Running MongoDB internally as the datastore behind your own
application and job queue does not create an SSPL obligation. The clause is aimed at companies that
resell a managed MongoDB-as-a-service, not at companies that simply run MongoDB.
* **A commercial license is available.** Organizations with a commercial agreement with MongoDB Inc.
can use MongoDB under that license instead, which removes the SSPL question entirely.
This licensing shift is also not unique to MongoDB. [Redis](https://redis.io/) (2024) and
[Elasticsearch](https://www.elastic.co/) (2021) both moved to SSPL, and both have since re-added an
OSI-approved option. MongoDB remains a deliberate design choice for Rocket Job: its atomic
`find_and_modify` is what lets thousands of workers claim jobs and slices without colliding, and it
spills from memory to disk, which is what makes processing very large files practical. See
[Architecture](architecture.html) for why the datastore is MongoDB specifically.
## Install MongoDB
Rocket Job stores all job data in [MongoDB](https://www.mongodb.com). The simplest way to run it
locally is in a Docker container. To install MongoDB without Docker, see the
[MongoDB Community downloads](https://www.mongodb.com/try/download/community).
### Run MongoDB in Docker
Install [Docker Desktop](https://www.docker.com/products/docker-desktop) if you do not already have
it, then start MongoDB:
~~~bash
docker run --name rocketjob_mongo -p 27017:27017 -d mongo:8.0
~~~
Useful follow-up commands:
~~~bash
# Stop the container, keeping its data
docker stop rocketjob_mongo
# Start it again later
docker start rocketjob_mongo
# Remove the container and destroy all of its data
docker rm rocketjob_mongo
~~~
For more on the official image, see [mongo on Docker Hub](https://hub.docker.com/_/mongo). In
production, sizing the WiredTiger cache is worthwhile, for example
`--wiredTigerCacheSizeGB 1.5`.
## Configure MongoDB
Rocket Job needs two MongoDB clients, defined in `config/mongoid.yml`:
* `rocketjob`: stores the jobs themselves.
* `rocketjob_slices`: stores the input and output slices for batch jobs.
Both can point at the same database in development. In production they can be split onto separate
databases, or even separate servers, to spread load. Use this file for both Rails and standalone
installations:
~~~yaml
# See: https://www.mongodb.com/docs/mongoid/current/reference/configuration/
client_options: &client_options
read:
mode: :primary
write:
w: 1
connect_timeout: 10
socket_timeout: 300
# Includes the time taken to re-establish after a replica-set refresh
wait_queue_timeout: 125
server_selection_timeout: 120
max_read_retries: 20
max_write_retries: 10
max_pool_size: 50
min_pool_size: 1
mongoid_options: &mongoid_options
preload_models: true
use_utc: true
development:
clients:
default: &default_development
uri: mongodb://127.0.0.1:27017/rocketjob_development
options:
<<: *client_options
rocketjob:
<<: *default_development
rocketjob_slices:
<<: *default_development
options:
<<: *mongoid_options
test:
clients:
default: &default_test
uri: mongodb://127.0.0.1:27017/rocketjob_test
options:
<<: *client_options
rocketjob:
<<: *default_test
rocketjob_slices:
<<: *default_test
options:
<<: *mongoid_options
production:
clients:
default: &default_production
uri: mongodb://user:secret@server.example.org:27017,server2.example.org:27017/rocketjob_production
options:
<<: *client_options
rocketjob:
<<: *default_production
rocketjob_slices:
<<: *default_production
# Optionally point slices at a different database or even a different server:
# uri: mongodb://user:secret@server3.example.org:27017/slices_production
options:
<<: *mongoid_options
~~~
If you already have a Mongoid configuration (for example from `bundle exec rails generate
mongoid:config`), just add the `rocketjob` and `rocketjob_slices` clients shown above to every
environment.
## Rails Installation
Add Rocket Job to an existing Rails 7.2 or newer application.
### 1. Add the gems
Add to the bottom of your `Gemfile`:
~~~ruby
gem "rails_semantic_logger"
gem "rocketjob"
~~~
~~~bash
bundle install
~~~
### 2. Configure MongoDB
Create `config/mongoid.yml` as shown in [Configure MongoDB](#configure-mongodb) above.
If you are running `Spring` (installed by default in Rails), restart it so the new configuration is
picked up:
~~~bash
bin/spring stop
~~~
### 3. Start a worker
~~~bash
bundle exec rocketjob
~~~
Or, if you have generated bundler binstubs:
~~~bash
bin/rocketjob
~~~
That is a complete Rails installation. Define jobs under `app/jobs` and queue them with
`MyJob.create!`. See the [Programmer's Guide](guide.html).
### Install the web interface
[Rocket Job Mission Control](mission_control.html) is a Rails engine that mounts into your
application.
Add the gem:
~~~ruby
gem "rocketjob_mission_control", "~> 6.0"
~~~
~~~bash
bundle install
~~~
Mount the engine in `config/routes.rb`:
~~~ruby
mount RocketJobMissionControl::Engine => "rocketjob"
~~~
Start the Rails server and open
[http://localhost:3000/rocketjob](http://localhost:3000/rocketjob):
~~~bash
bin/rails s
~~~
## Standalone Installation
Run Rocket Job without Rails.
### 1. Create the project
~~~bash
mkdir -p standalone/jobs standalone/config
cd standalone
~~~
### 2. Add the gem
Create `Gemfile`:
~~~ruby
source "https://rubygems.org"
gem "rocketjob"
~~~
~~~bash
bundle install
~~~
### 3. Configure MongoDB
Create `config/mongoid.yml` as shown in [Configure MongoDB](#configure-mongodb) above.
### 4. Write a job
Create `jobs/hello_world_job.rb`:
~~~ruby
class HelloWorldJob < RocketJob::Job
def perform
puts "Hello World"
end
end
~~~
### 5. Start a worker
From inside the `standalone` directory:
~~~bash
bundle exec rocketjob
~~~
### 6. Queue a job
Open another console (`bundle exec irb`) and queue the job:
~~~ruby
require "rocketjob"
# Log to development.log using the colorized formatter
SemanticLogger.add_appender(file_name: "development.log", formatter: :color)
SemanticLogger.default_level = :debug
# Load config/mongoid.yml for the development environment
RocketJob::Config.load!("development")
require_relative "jobs/hello_world_job"
HelloWorldJob.create!
~~~
The worker process picks up the job and logs something like:
~~~
I [job:5731...] HelloWorldJob -- Start #perform
Hello World
I [job:5731...] (0.120ms) HelloWorldJob -- Completed #perform
~~~
`RocketJob::Config.load!` reads `config/mongoid.yml` relative to the current directory by default.
Pass an explicit path as the second argument to load it from elsewhere, and a third argument to
load a [Symmetric Encryption](https://encryption.reidmorrison.com) configuration file.
### Standalone web interface
[Rocket Job Mission Control](mission_control.html) is a Rails engine, so running it standalone means
hosting it in a minimal "shell" Rails application.
Create the shell application:
~~~bash
gem install rails
rails new rjmc
cd rjmc
~~~
Add to the bottom of the `Gemfile`:
~~~ruby
gem "rails_semantic_logger"
gem "rocketjob"
gem "rocketjob_mission_control", "~> 6.0"
gem "puma"
~~~
~~~bash
bundle install
~~~
Mount the engine at the root in `config/routes.rb`:
~~~ruby
mount RocketJobMissionControl::Engine => "/"
~~~
Restart Spring:
~~~bash
bin/spring stop
~~~
Generate a Mongoid configuration file and edit it to add the `rocketjob` and `rocketjob_slices`
clients to every environment, as in [Configure MongoDB](#configure-mongodb):
~~~bash
bundle exec rails generate mongoid:config
~~~
Start the server and open [http://localhost:3000](http://localhost:3000):
~~~bash
bin/rails s
~~~
## Next steps
* [Programmer's Guide](guide.html): the full job API, fields, scheduling, throttling, and callbacks.
* [Batch Guide](batch.html): large files, tabular data, and parallel processing.
* [Mission Control](mission_control.html): the web interface.
* [Dirmon](dirmon.html): trigger jobs from arriving files.
---
## Programmer's Guide
This guide covers the full programming interface for writing and running simple Rocket Job jobs.
For jobs that process large files in parallel across many workers, see the
[Batch Guide](batch.html). For installation and configuration, see the
[Installation guide](installation.html).
## Writing Jobs
A job is a Ruby class that inherits from `RocketJob::Job` and implements, at a minimum, a `perform`
method. The work the job does goes inside `perform`.
Create the file `report_job.rb` in `app/jobs` in a Rails application, or in the `jobs` folder when
running standalone without Rails:
~~~ruby
class ReportJob < RocketJob::Job
def perform
puts "Hello World"
end
end
~~~
Start, or re-start, Rocket Job servers to pick up the new code:
~~~bash
bundle exec rocketjob
~~~
Enqueue the job for processing:
~~~ruby
ReportJob.create!
~~~
The next available worker on any server picks up the job, runs `perform`, and records the result.
**Note:** restart the Rocket Job servers any time a job's source code changes, so that the workers
load the new code.
### Running a job in a console
When running Rails, start a console to try out a job directly, without starting a Rocket Job server:
~~~bash
bundle exec rails console
~~~
Define the job in the console:
~~~ruby
class HelloJob < RocketJob::Job
def perform
puts "Hello World"
end
end
~~~
Run it inline in the current process:
~~~ruby
job = HelloJob.new
job.perform_now
# => Hello World
~~~
`perform_now` runs the job inline in the current process. It does not require the job to be saved
first, and it does not need a running Rocket Job server. Validations are still run before `perform`
is called. This approach is used heavily in tests so that a server is not needed to run them.
## The Job Lifecycle
Every job moves through a set of states, driven by a state machine. Knowing the states makes the
rest of this guide, and the [web interface](mission_control.html), easier to follow.
| State | Meaning
|:------------|:------------
| `queued` | Created and waiting for a worker. This is the initial state. A job whose `run_at` is in the future is `queued` and considered _scheduled_.
| `running` | A worker is currently processing the job.
| `completed` | Finished successfully. This is an end state. By default the job is then destroyed (see [Retention](#retention)).
| `failed` | Raised an exception. Retained so it can be retried or aborted.
| `paused` | Temporarily halted. Only [batch jobs](batch.html) (and jobs paused before they start) can be paused and later resumed.
| `aborted` | Cancelled and cannot be resumed. This is an end state.
The transitions between these states are `start`, `complete`, `fail`, `retry`, `pause`, `resume`,
`abort`, and `requeue`. Each transition has a matching pair of [callbacks](#callbacks), for example
`before_start` / `after_start`.
~~~mermaid
stateDiagram-v2
[*] --> queued : create
queued --> running : start
running --> completed : complete
completed --> [*]
running --> failed : fail
queued --> failed : fail
paused --> failed : fail
failed --> queued : retry
queued --> paused : pause
running --> paused : pause (pausable)
paused --> running : resume (if started)
paused --> queued : resume (if not started)
running --> queued : requeue (worker died)
queued --> aborted : abort
running --> aborted : abort
failed --> aborted : abort
paused --> aborted : abort
aborted --> [*]
~~~
Reading the diagram:
* A job is created `queued`, a worker picks it up with `start`, and on success it `complete`s. With
the default `destroy_on_complete` the `completed` job is then destroyed.
* Any exception during processing triggers `fail`. A `failed` job is retained so it can be `retry`ed
(back to `queued`) or `abort`ed.
* `pause` / `resume` temporarily halt a job. Only [batch jobs](batch.html), and any job paused before
it starts, are pausable while `running`; a job paused before it started resumes to `queued`, one
paused after starting resumes to `running`.
* `requeue` returns a `running` job to `queued`. Rocket Job does this automatically when the server
(worker) processing the job dies, so the job is retried elsewhere.
* `abort` cancels a job from almost any state. `completed` and `aborted` are the two end states.
Check the current state at any time:
~~~ruby
job.reload
job.state # => :running
job.running? # => true
job.completed? # => false
~~~
### Triggering a transition
Each transition is callable as a method on the job, and every one comes in two forms:
* `job.abort` runs the transition **in memory only**. The state field is updated on the instance,
but nothing is written to the database until you call `job.save!` yourself.
* `job.abort!` (the bang form) runs the transition **and persists** the job in one step.
~~~ruby
# In-memory only: the database still shows the old state
job.abort
job.save! # now the change is persisted
# Equivalent, in a single step
job.abort!
~~~
This applies to every transition, not just `abort`: `start`/`start!`, `complete`/`complete!`,
`fail`/`fail!`, `retry`/`retry!`, `pause`/`pause!`, `resume`/`resume!`, and `requeue`/`requeue!`. Use
the non-bang form when you want to make other changes to the job and save them together; use the bang
form for a one-shot transition. (Persistence is whiny: a failed save raises rather than returning
`false`.)
## Fields
Every job already has a set of standard fields, and custom fields can be added with the `field`
keyword.
### Standard Fields
These fields exist on every job. The first group can be set when the job is created:
| Field | Type | Default | Description
|:----------------------|:--------|:--------|:------------
| `description` | String | | Human readable description, shown in the web interface.
| `priority` | Integer | 50 | Business [priority](#business-priority) from 1 (highest) to 100 (lowest).
| `destroy_on_complete` | Boolean | true | Destroy the job once it completes. See [Retention](#retention).
| `run_at` | Time | | Do not run the job before this time. See [Delayed Processing](#delayed-processing).
| `expires_at` | Time | | Discard the job if it has not started by this time. See [Expiry](#expiry).
| `log_level` | Symbol | | Override the [log level](#logging) for this job. One of `:trace`, `:debug`, `:info`, `:warn`, `:error`, `:fatal`.
The remaining standard fields are read-only and maintained by Rocket Job itself:
| Field | Type | Description
|:-------------------|:--------|:------------
| `state` | Symbol | Current [state](#the-job-lifecycle). Do not modify directly.
| `created_at` | Time | When the job was created.
| `started_at` | Time | When processing started.
| `completed_at` | Time | When processing finished (also used for paused / aborted / failed times).
| `failure_count` | Integer | Number of times the job has failed.
| `worker_name` | String | Name of the worker processing, or that processed, the job.
| `percent_complete` | Integer | Estimated progress from 0 to 100. A job can update this while running.
| `exception` | Embedded | Details of the last exception, when the job has failed. See [Exception Handling](#exception-handling).
### User-Defined Fields
Add custom fields with the `field` keyword. A field has a name and a type:
~~~ruby
class ReportJob < RocketJob::Job
# Retain the job when it completes so its fields can be inspected later
self.destroy_on_complete = false
# Custom field called `username` with a type of `String`
field :username, type: String
def perform
logger.info "Username is #{username}"
# Perform work here
end
end
~~~
Set a field when the job is created:
~~~ruby
job = ReportJob.create!(username: "Jack Jones")
~~~
Retrieve the value:
~~~ruby
job.username
# => "Jack Jones"
~~~
Custom fields can also be read and set within the job itself. Set a field during `perform` to make
its value visible after the job completes:
~~~ruby
class ReportJob < RocketJob::Job
self.destroy_on_complete = false
field :username, type: String
field :user_count, type: Integer
def perform
# Read a supplied value
puts username
# Set a value so that it is visible after the job completes
self.user_count = 123
end
end
~~~
On completion the value can be viewed in [Mission Control](mission_control.html), or read
programmatically:
~~~ruby
job = ReportJob.completed.last
job.user_count
# => 123
~~~
### Field Types
Valid field types:
* Array
* Mongoid::Boolean
* Date
* DateTime
* Float
* Hash
* Integer
* BSON::ObjectId
* BSON::Binary
* Range
* Regexp
* String
* Mongoid::StringifiedSymbol
* Time
* TimeWithZone
**Note:** Ruby Symbols are deliberately not supported as a stored type. Use `String`, or
`Mongoid::StringifiedSymbol` when a value should behave like a symbol in Ruby but be stored as a
string.
**Note:** when using the `Hash` type, use only strings for key names, and key names must not contain
any `.` (periods):
~~~ruby
class ReportJob < RocketJob::Job
self.destroy_on_complete = false
field :statistics, type: Hash
def perform
# Fails to save: the key name contains periods
self.statistics = {"this.is.bad" => 20}
# Saves, but the symbol key is converted to a string. Not recommended:
self.statistics = {valid: 39}
# Saves correctly
self.statistics = {"valid" => 39}
end
end
~~~
### Field Defaults
A custom field can be given a default value:
~~~ruby
class ReportJob < RocketJob::Job
self.destroy_on_complete = false
field :username, type: String, default: "Joe Bloggs"
field :user_count, type: Integer, default: 0
def perform
puts username
self.user_count += 1
end
end
~~~
~~~ruby
job = ReportJob.new
job.username
# => "Joe Bloggs"
~~~
Defaults can be procs, so they are calculated at runtime instead of class-load time:
~~~ruby
# Sets `report_date` by default to the date when the job is created:
field :report_date, type: Date, default: -> { Date.today }
~~~
When the default is a proc or lambda, it has access to the job itself:
~~~ruby
field :report_date, type: Date, default: -> { new_record? ? Date.yesterday : Date.today }
~~~
Proc and lambda defaults are applied _after_ all other attributes are set. To apply the default
_before_ the other attributes are set, use `pre_processed: true`:
~~~ruby
field :report_date, type: Date, default: -> { new_record? ? Date.yesterday : Date.today }, pre_processed: true
~~~
A plain default is evaluated once, at class-load time. A proc or lambda default is evaluated every
time a job is created, which is usually what is intended:
~~~ruby
field :report_date, type: Date, default: Date.today # Evaluated once, when the class loads
field :report_date, type: Date, default: -> { Date.today } # Evaluated every time a job is created
~~~
### Field Settings
Fields support additional settings to control their behavior.
#### user_editable
By default, fields cannot be edited in [Mission Control](mission_control.html). To let web interface
users edit a field, both on the job and on a [DirmonEntry](dirmon.html), add `user_editable: true`:
~~~ruby
field :report_date, type: Date, user_editable: true
~~~
#### copy_on_restart
When a [scheduled job](#scheduled-jobs) creates its next instance, custom field values are not
carried across by default. Mark a field `copy_on_restart: true` to copy its value into the new
instance:
~~~ruby
field :report_date, type: Date, copy_on_restart: true
~~~
This is used by `RocketJob::Job#create_restart!`, which the [Cron](#scheduled-jobs) plugin relies on.
## Business Priority
Rocket Job runs jobs in business priority order. Priorities range from 1 to 100, where 1 is the
highest priority. Every job has a priority of 50 by default.
Priority based processing keeps workers fully utilized while ensuring business-critical work is
processed ahead of routine work.
Set the default priority for a job class:
~~~ruby
class ReportJob < RocketJob::Job
self.priority = 70
def perform
# Perform work here
end
end
~~~
Raise the priority for a single instance so that it jumps the queue:
~~~ruby
ReportJob.create!(priority: 5)
~~~
The priority can also be changed at runtime via [Mission Control](mission_control.html).
## Delayed Processing
Delay execution to a future time by setting `run_at`:
~~~ruby
ReportJob.create!(
# Only run this job 2 hours from now
run_at: 2.hours.from_now
)
~~~
A job whose `run_at` is in the future is _scheduled_: it stays `queued` until that time arrives, and
then runs as soon as a worker is available.
## Expiry
Sometimes a queued job is no longer relevant if processing has not started by a certain time. Set
`expires_at` and the job is discarded without processing if a worker has not picked it up by then:
~~~ruby
# Do not process this job if it is still queued 15 minutes from now
ReportJob.create!(expires_at: 15.minutes.from_now)
~~~
This is useful when workers are busy with higher priority jobs and the work would be stale by the
time it could run.
## Retention
By default, jobs are removed from the system automatically when they complete. To retain completed
jobs, set `destroy_on_complete` to false:
~~~ruby
class ReportJob < RocketJob::Job
# Retain the job when it completes
self.destroy_on_complete = false
def perform
# Perform work here
end
end
~~~
Retained completed jobs are visible in [Mission Control](mission_control.html).
**Note:** a job that fails is always retained, regardless of `destroy_on_complete`. Use
`RocketJob::Jobs::HousekeepingJob` to clear out old failed jobs that are not being retried.
## Collecting Output
When a job runs, its result is usually a side effect: rows written to a database, emails sent, and
so on. Sometimes it is useful to keep a result on the job itself, to take further action or to
display to a user. Store it in a custom field:
~~~ruby
class ReportJob < RocketJob::Job
# Retain the job after completion so the result can be read
self.destroy_on_complete = false
# Input field
field :count, type: Integer
# Output field
field :result, type: Hash
def perform
self.result = {calculation: count * 1000}
end
end
~~~
Queue the job:
~~~ruby
job = ReportJob.create!(count: 24)
~~~
Continue with other work, then read the result once the job has completed:
~~~ruby
if job.reload.completed?
puts "Job result: #{job.result.inspect}"
end
~~~
## Job Status
A full status snapshot is available at any time:
~~~ruby
# Refresh the in-memory copy of the job
job.reload
# Current state, for example: :queued, :running, :completed
puts "Job is: #{job.state}"
# Complete status information, as displayed in Mission Control
puts "Full job status: #{job.status.inspect}"
~~~
`duration` returns how long the job has been running, or took to run:
~~~ruby
puts "The job has been running for: #{job.duration}"
~~~
## Scheduled Jobs
Scheduled jobs run on a regular schedule, like a crontab. They are a strong alternative to cron:
they are visible in [Mission Control](mission_control.html), they appear in the failed jobs list if
they fail and can be retried, and they can be run immediately with the `Run` button in the web
interface.
Add the `RocketJob::Plugins::Cron` plugin and set a `cron_schedule`. When a scheduled job is
created, it is queued to run at the next occurrence of the schedule. When that instance completes,
or fails, a new instance is automatically scheduled for the following occurrence.
The next instance is only created once the current one has finished, so the system never runs two
instances of the same scheduled job at once. For example, a job that takes 10 minutes but is
scheduled every 5 minutes runs every 10 minutes.
There is no centralized scheduler and no scheduler process to start. Any Rocket Job worker can run a
scheduled job, so there is no single point of failure. With a Linux cron, if the server hosting the
crontab is down when a task is due, that task is missed; Rocket Job has no such gap.
Create a scheduled job that runs at 1am UTC every day:
~~~ruby
class MyCronJob < RocketJob::Job
include RocketJob::Plugins::Cron
# Default cron schedule
self.cron_schedule = "0 1 * * * UTC"
def perform
puts "DONE"
end
end
~~~
Queue it using its default schedule:
~~~ruby
MyCronJob.create!
~~~
Once a scheduled job is queued it should not be created again. In Rails a common technique is a
migration that creates the scheduled job in each environment:
~~~ruby
class CreateMyCronJob < ActiveRecord::Migration[7.2]
def up
MyCronJob.create!
end
def down
MyCronJob.delete_all
end
end
~~~
### Ad-hoc and scheduled in one job
A single job can serve both as a scheduled job and as an on-demand job, by leaving the
`cron_schedule` unset by default and supplying it only when scheduling:
~~~ruby
class ReportJob < RocketJob::Job
# No default cron_schedule, so the job can also be used for ad-hoc work
include RocketJob::Plugins::Cron
field :start_date, type: Date
field :end_date, type: Date
def perform
# Use `scheduled_at` to account for any delay in the job being picked up
self.start_date ||= scheduled_at.beginning_of_week.to_date
self.end_date ||= scheduled_at.end_of_week.to_date
puts "Running report, starting at #{start_date}, ending at #{end_date}"
end
end
~~~
Create a scheduled instance by supplying a `cron_schedule`:
~~~ruby
ReportJob.create!(cron_schedule: "0 1 * * * America/New_York")
~~~
Create an ad-hoc instance by leaving the `cron_schedule` out:
~~~ruby
ReportJob.create!(start_date: 30.days.ago, end_date: 10.days.ago)
~~~
### The cron_schedule format
The `cron_schedule` field has the following format:
* * * * * *
┬ ┬ ┬ ┬ ┬ ┬
│ │ │ │ │ │
│ │ │ │ │ └ Optional: Timezone, for example: 'America/New_York', 'UTC'
│ │ │ │ └───── day_of_week (0-7) (0 or 7 is Sun, or use 3-letter names)
│ │ │ └────────── month (1-12, or use 3-letter names)
│ │ └─────────────── day_of_month (1-31, L, -1..-31)
│ └──────────────────── hour (0-23)
└───────────────────────── minute (0-59)
* When specifying day of week, both day 0 and day 7 are Sunday.
* Ranges and lists of numbers are allowed.
* Ranges or lists of names are not allowed.
* Ranges can include steps, so `1-9/2` is the same as `1,3,5,7,9`.
* Months and days of the week can be specified by name, using the first three letters (case does
not matter).
* A `day_of_month` of `L` means the last day of the month.
* The timezone is recommended, to avoid issues with differing default timezones across servers and
environments. For the complete list, see the
[Wikipedia List of tz database time zones](https://en.wikipedia.org/wiki/List_of_tz_database_time_zones).
#### cron_schedule examples
| Description | cron_schedule
|:----------------------------------------------------------------------------------------------|:-------------
| Every minute |`* * * * *`
| Every 10 minutes |`*/10 * * * *`
| Every 30 minutes on the half hour |`0,30 * * * *`
| Every hour on the hour |`0 * * * *`
| Every day at 2am |`0 2 * * *`
| 5am and 5pm daily |`0 5,17 * * *`
| Every 4 hours |`* */4 * * *`
| Every month |`0 0 1 * *`
| On the 5th and the 6th of every month |`0 0 5,6 * *`
| Last day of the month |`0 12 L * *`
| 5 days before the end of the month |`0 0 -5 * *`
| Every January |`0 0 * Jan *`
| Every January, May and August |`0 0 * Jan,May,Aug *`
| Quarterly |`0 0 1 */3 *`
| Annually |`0 0 1 1 *`
| Every Sunday and Friday at 5pm |`0 17 * * Sun,Fri`
| First Monday of every month |`0 12 * * Mon#1`
| Third Monday of every month |`0 12 * * Mon#3`
| Last Sunday of every month |`0 12 * * Sun#-1`
| Fri, Sat and Sun at 3:30pm |`30 15 * * Fri,Sat,Sun`
| 4am and 5pm on Sunday and Monday only |`0 4,17 * * Sun,Mon`
| Every night from the 5th to the 12th |`30 0 5-12 * *`
| 10 days before the end of the month to 5 days before the end of the month |`0 0 -10--5 * *`
| Every second day, 10 days before the end of the month to 5 days before the end of the month |`0 0 -10--2/2 * *`
To try out a cron entry and see when it would next run:
~~~ruby
Fugit::Cron.new("*/5 * * * *").next_time.to_utc_time
~~~
Or relative to a specific time:
~~~ruby
current_time = Time.parse("2018-01-01 10:00:00")
Fugit::Cron.new("*/5 * * * *").next_time(current_time).to_utc_time
~~~
### Running and changing a scheduled job
Make a scheduled job run immediately, rather than waiting for its next occurrence:
~~~ruby
MyCronJob.queued.first.run_now!
~~~
Change the schedule of an existing scheduled job:
~~~ruby
job = MyCronJob.queued.first
job.cron_schedule = "* 1 * * * America/New_York"
job.save!
~~~
When the `cron_schedule` changes, the `run_at` is recalculated before saving, so the change takes
effect immediately.
### Scheduling options
The Cron plugin adds two further fields:
* `cron_singleton` (default `true`): prevent another instance of this job from being queued, running,
failed, or paused with the _same_ `cron_schedule`. An instance with a different schedule string is
still allowed.
* `cron_after_start` (default `true`): when `true`, the next instance is scheduled as soon as the
current one starts, so a long-running instance does not delay the next occurrence. When `false`,
the next instance is only scheduled once the current one completes, fails, or is aborted.
### Carrying field values across runs
When a scheduled job creates its next instance, custom field values are not carried over by default:
~~~ruby
class MyCronJob < RocketJob::Job
include RocketJob::Plugins::Cron
self.cron_schedule = "0 0 * * * UTC"
field :name, type: String
def perform
# Called every night at midnight UTC
end
end
~~~
~~~ruby
MyCronJob.create!(name: "Joe Bloggs")
~~~
The first run uses `name`, but the next scheduled instance loses it. Mark the field
`copy_on_restart: true` to carry the value forward:
~~~ruby
class MyCronJob < RocketJob::Job
include RocketJob::Plugins::Cron
self.cron_schedule = "0 0 * * * UTC"
# Retain the field value between scheduled instances
field :name, type: String, copy_on_restart: true
def perform
# Called every night at midnight UTC
end
end
~~~
### Notes
* When a scheduled job's time arrives, it runs only if a worker is available. If workers are busy
with higher priority jobs, it runs once those finish, or once their priority is lowered.
* A scheduled job is not rescheduled if it has passed its `expires_at`. This lets a scheduled job
destroy itself at a future date by setting `expires_at`.
* When a scheduled job fails, it creates a new scheduled instance and clears the `cron_schedule` on
the failed instance, so that retrying the failed instance does not create yet another schedule.
## Processing Window
A processing window ensures a job only runs between certain hours, regardless of when it was
created. This is useful for creating a job now that should only run later, during a specific window.
If the window is already open, the job can run immediately.
Examples:
* Process this job on Mondays between 8am and 10am.
* Run this job on the 1st of every month, from midnight, for the entire day.
Because the schedule supports timezones, it is easy to target UTC or any other zone.
~~~ruby
# Only run between 8:30am and 8:30pm Eastern. If it is after 8:30pm, schedule it
# to run at 8:30am the next day.
class BusinessHoursJob < RocketJob::Job
include RocketJob::Plugins::ProcessingWindow
# The start of the processing window
self.processing_schedule = "30 8 * * * America/New_York"
# How long the processing window stays open
self.processing_duration = 12.hours
def perform
# Job will only run between 8:30am and 8:30pm Eastern
end
end
~~~
**Note:** if a job is created during the window but, due to busy or unavailable workers, is not
processed before the window closes, it is re-queued for the beginning of the next window.
## Automatic Retry
To have a job automatically retry itself on failure, without any manual intervention, add the
`RocketJob::Plugins::Retry` plugin:
~~~ruby
class ReportJob < RocketJob::Job
include RocketJob::Plugins::Retry
def perform
# Perform work here
end
end
~~~
### Retry attempts
The default number of attempts before giving up is 25, which spans about 20 days because of the
exponential back-off between retries: the delay before retry `n` is `(n - 1)**4 + 5` seconds.
Change the number of attempts with `retry_limit`:
~~~ruby
class ReportJob < RocketJob::Job
include RocketJob::Plugins::Retry
# Maximum number of times to retry before giving up
self.retry_limit = 3
def perform
# Perform work here
end
end
~~~
Override the limit per instance, or disable retries entirely for one instance with `retry_limit: 0`:
~~~ruby
ReportJob.create!(retry_limit: 10)
ReportJob.create!(retry_limit: 0)
~~~
### Notes
* Each retry is scheduled to run in the future using an exponential back-off, to avoid overwhelming
a failed resource. While waiting to retry, the job appears as `queued` (or `running`), not
`failed`, in [Mission Control](mission_control.html).
* A job is not retried if it has expired, if it exceeds its `retry_limit`, or if it fails
validations when the retry is attempted (an error is logged and the job is not retried).
* When a job is retried, its previous exception is logged and the `exception` attribute is cleared.
## Singleton
The Singleton plugin ensures that only one instance of a job class is `running`, `queued`, or
`paused` at a time. Saving a new instance fails validation while another is active:
~~~ruby
class ReportJob < RocketJob::Job
include RocketJob::Plugins::Singleton
def perform
# Perform work here
end
end
~~~
## Throttling
Throttles limit how much work of a given kind runs at once, so jobs cannot overwhelm shared
resources.
Whenever a throttle holds a job back, the reason is recorded on the job in the `throttled_by` field
(with `throttled_at`) and shown in Mission Control, so it is clear why a job is sitting in `queued`
rather than running. The reason is cleared automatically once the job is allowed to start.
### Throttle Running Jobs
Because it is common to run hundreds or thousands of workers, an unbounded job class could mount a
distributed denial of service against a shared resource. Limit how many instances of a job class run
at the same time with `throttle_running_jobs`:
~~~ruby
class MyJob < RocketJob::Job
# Maximum number of jobs of this class to run at the same time
self.throttle_running_jobs = 25
def perform
# ...
end
end
~~~
Jobs in excess of the limit stay `queued` and only start once the running count drops below
`throttle_running_jobs`.
To throttle across several job classes together, set a shared `throttle_group` on each; the limit
then applies to the combined group rather than per class.
**Notes:**
* The number of running jobs will not exceed the limit.
* A job may briefly appear to run over the limit and then immediately return to `queued`. This is
expected: a worker claims the job and only then verifies the throttle, which prevents another
worker from grabbing the same job and exceeding the limit.
### Throttle Dependent Jobs
Prevent a job from running while instances of other job classes are running. This job stays queued
while any `FirstJob` or `SecondJob` is running:
~~~ruby
class MyJob < RocketJob::Job
include RocketJob::Plugins::ThrottleDependentJobs
self.dependent_jobs = ["FirstJob", "SecondJob"]
def perform
# ...
end
end
~~~
The dependent job classes can also be declared with `depends_on_job`:
~~~ruby
class MyJob < RocketJob::Job
include RocketJob::Plugins::ThrottleDependentJobs
depends_on_job FirstJob, SecondJob
def perform
# ...
end
end
~~~
### Custom Throttles
Define custom throttles with `define_throttle`. The named method returns true when the throttle is
exceeded, in which case the job is left queued and re-checked later (every
`RocketJob::Config.re_check_seconds`, which defaults to 60 seconds):
~~~ruby
class MyJob < RocketJob::Job
# Do not run this job when the MySQL replica delay exceeds 5 minutes
define_throttle :mysql_throttle_exceeded?
def perform
# ...
end
private
# Returns true if the MySQL replica delay exceeds 5 minutes
def mysql_throttle_exceeded?
status = ActiveRecord::Base.connection.select_one("show slave status")
seconds_delay = Hash(status)["Seconds_Behind_Master"].to_i
seconds_delay >= 300
end
end
~~~
Pass a `description:` to control the reason shown in Mission Control when this throttle holds the job
back. It can be a String, or a Proc that receives the job and returns a String so the reason can
include runtime detail:
~~~ruby
define_throttle :mysql_throttle_exceeded?,
description: "Throttled: MySQL replica delay exceeds 5 minutes"
~~~
When no `description:` is given, a humanized form of the method name is used. The same `description:`
option is available on `define_batch_throttle` for batch jobs.
## Transactions
The `RocketJob::Plugins::Transaction` plugin wraps every `perform` call in an Active Record
transaction. If `perform` raises an exception, any database changes are rolled back. For
[batch jobs](batch.html), the transaction wraps each slice, so an entire slice either succeeds or is
rolled back.
~~~ruby
# Update a User and create an Audit entry as a single database transaction.
# If Audit.create! fails, the user change is also rolled back.
class MyJob < RocketJob::Job
include RocketJob::Plugins::Transaction
def perform
u = User.find_by(name: "Jack")
u.age = 21
u.save!
Audit.create!(table: "user", description: "Changed age to 21")
end
end
~~~
**Performance:**
* On CRuby an empty transaction block takes about 1ms.
* On JRuby an empty transaction block takes about 55ms.
**Note:** this plugin is only activated if Active Record has already been loaded.
## Persistence
The persistence methods follow the conventions used by other ActiveRecord-like frameworks.
### Job.create!
Enqueue a single job for processing. Raises an exception on a validation error.
~~~ruby
ReportJob.create!(report_date: Date.yesterday)
~~~
### Job#save!
Enqueue a new job, or save changes to an existing one, atomically. Raises an exception on a
validation error.
~~~ruby
job = ReportJob.new
job.report_date = Date.yesterday
job.save!
~~~
### Job#update_attributes!
Update the supplied attributes, along with any other dirty fields. Raises an exception on a
validation error.
~~~ruby
job.update_attributes!(report_date: Date.yesterday)
~~~
### Job#update_attribute
Update a single attribute, bypassing validations.
~~~ruby
job.update_attribute(:report_date, Date.yesterday)
~~~
### Job#delete
Delete the job from the database _without_ running callbacks.
~~~ruby
job.delete
~~~
### Job#destroy
Delete the job from the database, running callbacks.
~~~ruby
job.destroy
~~~
### Job.delete_all
Delete jobs from the database _without_ running callbacks. Scope it to a job class, or call it on
`RocketJob::Job` for all jobs.
~~~ruby
ReportJob.delete_all
RocketJob::Job.delete_all
~~~
### Job.destroy_all
Delete jobs from the database, running callbacks. Scope it to a job class, or call it on
`RocketJob::Job` for all jobs.
~~~ruby
ReportJob.destroy_all
RocketJob::Job.destroy_all
~~~
## Queries
Beyond [Mission Control](mission_control.html), it is often useful to access jobs programmatically
while they run. Because each job is a single MongoDB document, everything about a job is available
through ordinary queries.
Find the most recently submitted job:
~~~ruby
job = RocketJob::Job.last
~~~
Find a specific job by id:
~~~ruby
job = RocketJob::Job.find("55aeaf03a26ec0c1bd00008d")
~~~
Change its priority:
~~~ruby
job = RocketJob::Job.find("55aeaf03a26ec0c1bd00008d")
job.priority = 32
job.save!
~~~
Or update an attribute directly, skipping the separate save:
~~~ruby
job = RocketJob::Job.find("55aeaf03a26ec0c1bd00008d")
job.update_attributes(priority: 32)
~~~
How long has the last job been running?
~~~ruby
job = RocketJob::Job.last
puts "The job has been running for: #{job.duration}"
~~~
How many `MyJob` jobs are currently being processed?
~~~ruby
count = MyJob.running.count
~~~
Retry all failed jobs in the system:
~~~ruby
RocketJob::Job.failed.each(&:retry!)
~~~
Is a particular job still running?
~~~ruby
job = RocketJob::Job.find("55aeaf03a26ec0c1bd00008d")
if job.completed?
puts "Finished!"
elsif job.running?
puts "The job is being processed by worker: #{job.worker_name}"
end
~~~
The state scopes (`queued`, `running`, `completed`, `failed`, `paused`, `aborted`) and the
`scheduled` and `queued_now` scopes are all available. For full query syntax, see the
[Mongoid Queries documentation](https://www.mongodb.com/docs/mongoid/current/reference/queries/).
### Querying custom fields
Custom fields can be used in queries to find a specific instance of a job class:
~~~ruby
class ReportJob < RocketJob::Job
self.destroy_on_complete = false
field :report_date, type: Date, default: -> { Date.today }
def perform
puts report_date
end
end
~~~
~~~ruby
job = ReportJob.where(report_date: Date.yesterday).first
~~~
## Callbacks
Callbacks let custom behavior run at many points in the job lifecycle.
Perform callbacks:
* `before_perform`
* `after_perform`
* `around_perform`
Persistence callbacks:
* `after_initialize`
* `before_validation`
* `after_validation`
* `before_save`
* `before_create`
* `after_create`
* `after_save`
Lifecycle (state transition) callbacks, one pair per [state transition](#the-job-lifecycle):
* `before_start` / `after_start`
* `before_complete` / `after_complete`
* `before_fail` / `after_fail`
* `before_retry` / `after_retry`
* `before_pause` / `after_pause`
* `before_resume` / `after_resume`
* `before_abort` / `after_abort`
Send an email when a job starts, completes, fails, or aborts:
~~~ruby
class MyJob < RocketJob::Job
field :email_recipients, type: Array
after_start :email_started
after_complete :email_completed
after_fail :email_failed
after_abort :email_aborted
def perform
# ...
end
private
def email_started
MyJob.started(email_recipients, self).deliver
end
def email_completed
MyJob.completed(email_recipients, self).deliver
end
def email_failed
MyJob.failed(email_recipients, self).deliver
end
def email_aborted
MyJob.aborted(email_recipients, self).deliver
end
end
~~~
Callbacks can be used to insert "middleware" into a single job class, or into all jobs. For example,
an `after_fail` callback can implement a custom retry policy, such as retrying immediately up to
three times.
Before callbacks run in the order they are defined. After callbacks run in the _reverse_ order to
which they were defined:
~~~
before_1
before_2
perform
after_2
after_1
~~~
A full example, including around callbacks:
~~~ruby
class MyJob < RocketJob::Job
before_perform do
puts "BEFORE 1"
end
around_perform do |job, block|
puts "AROUND 1 BEFORE"
block.call
puts "AROUND 1 AFTER"
end
before_perform do
puts "BEFORE 2"
end
after_perform do
puts "AFTER 1"
end
around_perform do |job, block|
puts "AROUND 2 BEFORE"
block.call
puts "AROUND 2 AFTER"
end
after_perform do
puts "AFTER 2"
end
def perform
puts "PERFORM"
23
end
end
~~~
Run it inline, without workers:
~~~ruby
MyJob.new.perform_now
~~~
Output:
~~~
BEFORE 1
AROUND 1 BEFORE
BEFORE 2
AROUND 2 BEFORE
PERFORM
AFTER 2
AROUND 2 AFTER
AFTER 1
AROUND 1 AFTER
~~~
For more on callbacks, see the
[Mongoid Callbacks documentation](https://www.mongodb.com/docs/mongoid/current/reference/callbacks/).
## Validations
The usual [Active Model validations](https://guides.rubyonrails.org/active_record_validations.html)
are available, since jobs expose Active Model:
~~~ruby
class ReportJob < RocketJob::Job
field :login, type: String
field :count, type: Integer
validates_presence_of :login
validates :count, inclusion: 1..100
end
~~~
Validations run before a job is saved and before `perform_now` runs the job inline, so a malformed
job is rejected up front rather than mid-run.
## Exception Handling
When a job fails, the exception and its full backtrace are stored on the job to aid problem
determination:
~~~ruby
if job.reload.failed?
puts "Job failed with: #{job.exception.klass}: #{job.exception.message}"
puts "Backtrace:"
puts job.exception.backtrace.join("\n")
end
~~~
## Thread Safety
Each Rocket Job server process runs a pool of worker threads, one job per thread, all in the same
process. Many jobs therefore run `perform` concurrently, so a job's `perform` method must be
thread-safe. See [Architecture and Internals](architecture.html) for why Rocket Job uses threads.
Each job runs on its own instance, so ordinary instance state inside `perform` (the job's own
fields and instance variables) is safe. What is not safe is shared mutable state:
* Do not write to global variables or mutable class-level state from `perform`. Two threads can
touch them at once.
* Make any shared cache thread-safe. A lazy `@@cache ||= ...` on shared class state can race;
initialize it at load time, or use a thread-safe structure such as `Concurrent::Map` from
`concurrent-ruby`, which Rocket Job already depends on.
* Any third party client called inside `perform` must itself be thread-safe, or be created per call.
~~~ruby
class ReportJob < RocketJob::Job
def perform
# Safe: local and instance state, scoped to this job instance / thread
rows = Report.rows_for(report_date)
self.row_count = rows.size
end
end
~~~
## Extending Jobs with Plugins
`RocketJob::Job` is composed from plugin modules (see
[the composition model](architecture.html#the-job-is-a-composition-of-plugins)). Custom behavior can be
packaged the same way, as an `ActiveSupport::Concern` that adds fields, callbacks, validations, and
methods to any job that includes it.
For example, a reusable plugin that emails a list of recipients whenever a job fails:
~~~ruby
require "active_support/concern"
module EmailOnFailure
extend ActiveSupport::Concern
included do
# Add a persisted, user-editable field to every job that includes this plugin
field :email_recipients, type: Array, default: []
# Hook into the job lifecycle
after_fail :email_failure
end
private
def email_failure
return if email_recipients.empty?
JobMailer.failed(email_recipients, self).deliver_now
end
end
~~~
Include it in any job:
~~~ruby
class ReportJob < RocketJob::Job
include EmailOnFailure
def perform
# ...
end
end
~~~
~~~ruby
ReportJob.create!(email_recipients: ["ops@example.com"])
~~~
Before writing a plugin, check whether a built-in one already covers the need. Rocket Job ships
optional plugins under `RocketJob::Plugins` ([Cron](#scheduled-jobs), [Singleton](#singleton),
[Retry](#automatic-retry), [ProcessingWindow](#processing-window),
[ThrottleDependentJobs](#throttle-dependent-jobs), [Transaction](#transactions)) and batch plugins
under `RocketJob::Batch`. For example, include `RocketJob::Plugins::Singleton` rather than
hand-rolling a singleton validation.
## Logging
Every job has a `logger`, provided by [Semantic Logger](https://logger.reidmorrison.com), with the job's
class name and id already tagged onto each entry:
~~~ruby
class ReportJob < RocketJob::Job
def perform
logger.info "Starting report"
logger.measure_info("Built report") do
# ... work whose duration is logged ...
end
end
end
~~~
Rocket Job automatically logs the start and completion of every `perform`, including its duration,
which is also emitted as a metric for systems such as statsd.
The `log_level` field overrides the log level for a single job, which is useful for quietening a
noisy job or, conversely, turning up logging to `:trace` to debug one job:
~~~ruby
# Only log warnings and above for this job instance
ReportJob.create!(log_level: :warn)
~~~
For full logging configuration, see the [Semantic Logger documentation](https://logger.reidmorrison.com).
## Writing Tests
### In-memory jobs
Jobs can be created and run entirely in memory, without being persisted. This is useful for tests,
for trying out jobs in a console, and even, in production, for running a diagnostic job in a console
without active workers picking it up.
~~~ruby
class ReportJob < RocketJob::Job
# Retain the job on completion
self.destroy_on_complete = false
def perform
puts "Hello World"
45
end
end
~~~
Create an in-memory instance with `.new` instead of `.create!`:
~~~ruby
job = ReportJob.new
~~~
Run the whole job in memory with `#perform_now`. For a simple job, it returns the value that
`perform` returned:
~~~ruby
job.perform_now
# => 45
~~~
The job should complete successfully:
~~~ruby
job.completed?
# => true
~~~
If it failed in memory, inspect its attributes:
~~~ruby
p(job.attributes) if job.failed?
~~~
### Minitest example
A Minitest test for the `ReportJob` above:
~~~ruby
require_relative "test_helper"
class ReportJobTest < Minitest::Test
describe ReportJob do
# Create an in-memory instance of the ReportJob
let(:report_job) { ReportJob.new }
describe "#perform_now" do
it "returns 45" do
# A new job is immediately in queued state
assert report_job.queued?
# perform_now returns the value that perform returned
assert_equal 45, report_job.perform_now
# The job should complete successfully
assert report_job.completed?, -> { report_job.attributes }
end
end
end
end
~~~
## Command Line Interface
Rocket Job ships with the `rocketjob` command for starting and managing servers.
### Starting a server
Start a server with the default of 10 workers:
~~~bash
bundle exec rocketjob
~~~
Start a server with 2 workers:
~~~bash
bundle exec rocketjob --workers 2
~~~
### Limiting which jobs a server runs
A server can be restricted to a subset of job classes, or to jobs matching a query. This is useful
for dedicating servers to particular workloads.
Run only `DirmonJob` and `WeeklyReportJob` (the filter is a case-insensitive regular expression):
~~~bash
bundle exec rocketjob --include "DirmonJob|WeeklyReportJob"
~~~
Run everything _except_ those classes:
~~~bash
bundle exec rocketjob --exclude "DirmonJob|WeeklyReportJob"
~~~
Restrict to jobs matching a MongoDB query, supplied as JSON. For example, only high priority jobs:
~~~bash
bundle exec rocketjob --where '{"priority":{"$lte":25}}'
~~~
**Note:** regular expressions and JSON must be quoted and escaped appropriately for the shell.
### Server options
| Option | Description
|:--------------------------------|:------------
| `-n`, `--name NAME` | Unique name of this server. Default: `host_name:PID`.
| `-w`, `--workers COUNT` | Number of worker threads to start.
| `--include REGEXP` | Only run job classes matching this case-insensitive regular expression.
| `-E`, `--exclude REGEXP` | Do not run job classes matching this case-insensitive regular expression.
| `-W`, `--where JSON` | Only run jobs matching this MongoDB query filter, as a JSON string.
| `-q`, `--quiet` | Write only to the log file, not stdout. Needed when running as a daemon.
| `-d`, `--dir DIR` | Directory of the Rails app, if not the current directory.
| `-e`, `--environment ENV` | Environment to run in. Default: `RAILS_ENV` or `RACK_ENV` or `development`.
| `-l`, `--log_level LEVEL` | Log level: `trace`, `debug`, `info`, `warn`, `error`, or `fatal`.
| `-f`, `--log_file FILE` | Log file to write to. Default: `log/.log`.
| `--pidfile PATH` | Write a pidfile to PATH.
| `-m`, `--mongo FILE` | Mongoid config file. Default: `config/mongoid.yml`.
| `-s`, `--symmetric-encryption FILE` | Symmetric Encryption config file. Default: `config/symmetric-encryption.yml`.
| `-v`, `--version` | Print the Rocket Job version.
### Managing running servers
These commands send an event to running servers, coordinated through MongoDB. Each takes an optional
complete or partial server name; with no name, the action applies to all servers.
| Option | Description
|:--------------------------|:------------
| `--list [FILTER]` | List active servers, optionally filtered by name.
| `--refresh [SECONDS]` | When listing, refresh every SECONDS (default 1 second).
| `--stop [SERVER_NAME]` | Stop server(s) once their in-process workers have finished.
| `--kill [SERVER_NAME]` | Hard kill server(s).
| `--pause [SERVER_NAME]` | Pause server(s).
| `--resume [SERVER_NAME]` | Resume paused server(s).
| `--dump [SERVER_NAME]` | Have server(s) write a worker thread dump to their log file.
## Next steps
* [Batch Guide](batch.html): process large files in parallel across many workers.
* [Dirmon](dirmon.html): trigger jobs automatically when files arrive.
* [Mission Control](mission_control.html): the web interface.
* [Installation](installation.html): Rails, standalone, and the web interface.
---
## Batch Jobs Guide
This guide covers batch jobs: jobs that process a large workload in parallel across many workers.
For the conventional single-worker job API (fields, scheduling, throttling, callbacks, queries), see
the [Programmer's Guide](guide.html).
## What is a batch job?
A regular [job](guide.html) runs on a single worker. A batch job breaks its input up into *slices*
so that many workers, often across hundreds of containers, process different parts of the work at
the same time.
Turn any job into a batch job by including `RocketJob::Batch` and writing a `perform` that handles a
single *record*:
~~~ruby
class ReverseJob < RocketJob::Job
include RocketJob::Batch
# Keep the job after it finishes so the output can be downloaded
self.destroy_on_complete = false
# Number of records per slice (the default)
input_category slice_size: 100
# Collect the value returned by each perform call as output
output_category
def perform(line)
# Called once per record, spread across all available workers
line.reverse
end
end
~~~
A few terms:
* A **record** is one unit of work passed to `perform`. It is usually a line or row from a file, but
can be any value that serializes to BSON (a String, Hash, Array, Integer, and so on).
* A **slice** is a group of records, 100 by default, that one worker claims and processes together.
* The job's input is uploaded into a dedicated MongoDB collection and divided into slices. For
example, a 1,000,000 line file with the default `slice_size` of 100 becomes 10,000 slices.
Because the work is sliced, a batch job can be **paused, resumed, or aborted as a whole**, and if
any slices fail, all of them can be retried by retrying the job. A running batch job is also
**interrupted by a higher priority job**: low priority jobs use all available workers until more
important work arrives, then resume once it is done. See [Business Priority](guide.html#business-priority).
## Your first batch job
Using the `ReverseJob` above, queue some records for processing. The block form of `upload` hands you
a writer that you append records to one at a time:
~~~ruby
words = %w[these are some words to be processed across many workers]
job = ReverseJob.new
job.upload do |records|
words.each { |word| records << word }
end
job.save!
~~~
Once the job completes, read the output (see [Collecting output](#collecting-output)):
~~~ruby
job.output.each do |slice|
slice.each { |record| puts record }
end
~~~
## Uploading input data
Input data is uploaded into the job before it is saved. Rocket Job stores it in a MongoDB collection
unique to that job, and removes each slice as soon as it is processed. Failed slices stay in the
collection, marked as failed, holding the exception and the name of the worker that was processing
them.
Uploading the data into the job, rather than referencing an external file, has several benefits:
* Workers do not need shared access to the original file or data store.
* The file can be decompressed or decrypted once, up front, before it is sliced.
* No separate data store is needed to hold the job's input.
* Each slice has its own state, so it can fail independently and carry its own exception.
Data can be uploaded from a file, an Active Record query, a Mongoid query, an integer range, or a
block of code.
### Files
`upload` streams an entire file into the job, one record per line by default, and returns the number
of records uploaded. Very large files are streamed rather than loaded into memory, so files far
larger than RAM can be uploaded.
~~~ruby
job = ReverseJob.new
job.upload("myfile.txt")
job.save!
~~~
Rocket Job auto-detects compression and encryption from the file name and decodes it before slicing.
It has built-in support for:
* `Zip` files (add the `rubyzip` gem on CRuby; JRuby uses native Java Zip)
* `GZip` files
* files encrypted with [Symmetric Encryption](https://encryption.reidmorrison.com)
* delimited files (Windows CR/LF or Linux LF line endings, auto-detected, or a custom delimiter)
* fixed-length record files
~~~ruby
# Auto-detected from the file extension:
job.upload("myfile.csv.zip") # Zip
job.upload("myfile.csv.gz") # GZip
job.upload("myfile.csv.zip.enc") # Encrypted Zip
~~~
Override the detected streams explicitly when the file name does not reflect the contents:
~~~ruby
job.upload("myfile.ze", streams: [:zip, :enc])
~~~
Useful `upload` keyword options:
| Option | Description
|:---------------|:------------
| `category` | Which input category to load into. Default: `:main`.
| `stream_mode` | `:line` (default), `:array`, or `:hash`. See [input categories](#input-categories).
| `file_name` | Override the file name used to infer format and streams.
| `delimiter` | Record delimiter. Default: auto-detect line endings.
| `on_first` | A lambda called with the first line, for example to capture a header.
Files are read as UTF-8 text, since MongoDB only stores UTF-8 strings, and a UTF-8 byte order mark
at the start of the file (as Excel writes) is removed. A file that is not valid UTF-8 raises
`Encoding::UndefinedConversionError` and nothing is uploaded. For files in another encoding, set the
`encoding` of the input category, which converts their records to UTF-8:
~~~ruby
class LegacyImportJob < RocketJob::Job
include RocketJob::Batch
# The files that this job receives are saved by Excel on Windows.
input_category format: :csv, encoding: "Windows-1252"
end
~~~
The category's encoding is saved with the job, so it also applies when a worker uploads the file, such
as a job started by [Dirmon](dirmon.html), or a `ConversionJob`. To read one file in another encoding,
set the encoding on the path instead, which takes the place of the category's:
~~~ruby
job.upload(IOStreams.path("legacy.csv").encoding("Windows-1252:UTF-8"))
~~~
Tabular formats, such as CSV, remove non-printable characters and characters that are not valid in
the file's encoding. A file in another encoding then loses those characters without any error, so when
its records must be complete, set the input category's `invalid_characters` to `:raise`, which fails the
upload with `IOStreams::Errors::InvalidEncoding`, naming the line of the first one, or to `:replace`,
which replaces each with `�` (U+FFFD) so that it can be seen in the record. Binary files cannot be
uploaded as records.
~~~ruby
input_category format: :csv, invalid_characters: :raise
~~~
Fixed width files are read as ASCII, as most are written by programs whose sizes count bytes, such as
those on a mainframe. A file with any other character raises `IOStreams::Errors::InvalidEncoding` and
nothing is uploaded, until its encoding is set: for example the input category's `encoding:
"ISO-8859-1"`, or `"IBM037"` for EBCDIC, or on the path, such as `encoding("UTF-8")` when its sizes count
UTF-8 characters, or `encoding(replace: " ")` to replace such characters with spaces. Non-printable
characters, such as NUL padding, are replaced with spaces so that the columns stay in place. Fixed width
output is downloaded as ASCII too, unless the output category's `encoding`, or the encoding of the
download path, is set.
A Zip stream must contain only one file; the first file found is loaded. CSV and other tabular
parsing is deliberately left to the workers (see [Reading tabular files](#reading-tabular-files)),
so by default a file is uploaded a raw line at a time.
For the full list of supported file types and transformations, see
[IOStreams](https://iostreams.reidmorrison.com).
### Active Record queries
`upload_arel` uploads the result of an Active Record query. By default it uploads only the `:id` of
each row, adding it to the select list to reduce overhead:
~~~ruby
# Upload the ids of all US users
job.upload_arel(User.where(country_code: "US"))
~~~
Supply column names to upload more than the id:
~~~ruby
job.upload_arel(User.where(country_code: "US"), :user_name, :zip_code)
~~~
Pass a block to transform each model into the record to upload:
~~~ruby
job.upload_arel(User.where(country_code: "US")) { |user| user.email }
~~~
### Mongoid queries
`upload_mongo_query` uploads the result of a MongoDB query. It reads the collection directly, rather
than building a Mongoid model per document, to avoid that overhead:
~~~ruby
# Upload the ids of all users in Florida
job.upload_mongo_query(User.where(state: "FL"))
# Upload an additional field
job.upload_mongo_query(User.where(state: "FL"), :zip_code)
~~~
When a block is supplied it receives each document and returns the record to upload. The returned
value must serialize to BSON (`Hash`, `Array`, `String`, `Integer`, `Float`, `Symbol`, `Regexp`,
`Time`; not `Date`). With a `Hash`, keys must be strings, not symbols.
### Integer ranges
`upload_integer_range` uploads a range of integers efficiently, which is ideal for driving work off a
contiguous range of ids:
~~~ruby
job.upload_integer_range(1, 1_000_000)
~~~
`upload_integer_range_in_reverse_order` does the same but processes the highest ids first. A plain
`Range` can also be passed straight to `upload`:
~~~ruby
job.upload(1..1_000_000)
~~~
### A block
When `upload` is given a block, it yields a writer to which records are appended one at a time:
~~~ruby
job.upload do |writer|
10.times { |i| writer << i }
end
~~~
Text in a record must be UTF-8, since MongoDB only stores UTF-8. A string in another encoding, such as
ISO-8859-1 from a database connection, is converted, but a binary string, or one that is not valid
UTF-8, raises an `EncodingError` that names the number of the first such record, and nothing is
uploaded. Convert such text first, such as `text.encode("UTF-8", "Windows-1252")`.
## Input categories
The `input_category` class method configures how uploaded data is sliced and parsed. With no
arguments, a job has a single input category named `:main` with the defaults below.
~~~ruby
class MyJob < RocketJob::Job
include RocketJob::Batch
input_category slice_size: 500, serializer: :compress
def perform(record)
# ...
end
end
~~~
Input category options:
| Option | Default | Description
|:-------------------|:------------|:------------
| `name` | `:main` | Name of the category. Use additional names for secondary input collections.
| `slice_size` | `100` | Number of records per slice.
| `serializer` | `:compress` | Slice serialization: `:none`, `:compress`, or `:encrypt`. See [Compression and encryption](#compression-and-encryption).
| `format` | `nil` | Parse each record before `perform`: `nil` (raw line), `:auto`, or a tabular format such as `:csv`. See [Reading tabular files](#reading-tabular-files).
| `format_options` | `nil` | Format-specific options, for example a `:layout` for `:fixed`.
| `encoding` | `nil` | The encoding of the files, such as `"Windows-1252"`, which is converted to UTF-8. `nil` reads UTF-8, or the format's own encoding, such as ASCII for `:fixed`. Name the byte order of UTF-16 or UTF-32, such as `"UTF-16LE"`. See [Files](#files).
| `invalid_characters` | `nil` | What to do with a character that is not valid in the file's encoding: `:remove`, `:replace` with U+FFFD, or `:raise`. `nil` removes them from tabular formats, such as CSV, and raises for `:fixed` and lines.
| `columns` | `nil` | Header columns, when the file has no header row.
| `mode` | `:line` | How a file is uploaded: `:line`, `:array`, or `:hash`.
| `allowed_columns` | `nil` | Restrict tabular input to these columns. See [Validating columns](#validating-columns).
| `required_columns` | `nil` | Tabular columns that must be present, or an exception is raised.
| `skip_unknown` | `false` | When `allowed_columns` is set, skip unknown columns instead of raising.
| `header_cleanser` | `:default` | Cleanse tabular header column names (`:default`) or leave them as-is (`:none`).
The `mode` option controls how a file is read during upload:
* `:line` (default) uploads a raw line (String) at a time. This is the most performant, since each
worker parses its own lines.
* `:array` parses each line into an Array before uploading. The whole file is parsed up front, so an
invalid file is detected before processing starts. Not recommended for very large files.
* `:hash` parses each line into a Hash before uploading. Like `:array`, but slightly less efficient.
The `stream_mode` option of `upload` overrides `mode` for that upload.
## Collecting output
To keep the value returned by `perform`, register an output category with `output_category`. With no
arguments it registers a single output category named `:main`:
~~~ruby
class ReverseJob < RocketJob::Job
include RocketJob::Batch
self.destroy_on_complete = false
output_category
def perform(line)
line.reverse
end
end
~~~
Read the collected output once the job has completed:
~~~ruby
job.output.each do |slice|
slice.each { |record| puts record }
end
~~~
Or download it straight to a file, optionally compressed on the way out:
~~~ruby
job.download("reversed.txt.gz")
~~~
### Output ordering
The output slices and records are in exactly the same order as the records were uploaded, which
makes it easy to line an output record up with its input record. Two things change that alignment:
* An input file with a header row (for example CSV) whose output format does not have one (for
example JSON) shifts every output record by one line.
* Setting `nils: false` on the output category (the default) skips records for which `perform`
returned `nil`, so those positions are absent from the output.
### Waiting for completion
Output can be queried at any time, but it is only complete once the job has finished. To wait
programmatically:
~~~ruby
loop do
sleep 1
job.reload
break unless job.running? || job.queued?
end
~~~
### Output categories
The `output_category` class method accepts these options:
| Option | Default | Description
|:-----------------|:------------|:------------
| `name` | `:main` | Name of the category. Register additional names for [multiple output files](#multiple-output-files).
| `serializer` | `:compress` | Slice serialization: `:none`, `:compress`, `:encrypt`, `:bz2`, or `:encrypted_bz2`. See [Fast bzip2 output files](#fast-bzip2-output-files).
| `format` | `nil` | Render each result: `nil`, `:auto`, or a tabular format such as `:csv`. See [Writing tabular files](#writing-tabular-files).
| `format_options` | `nil` | Format-specific options.
| `encoding` | `nil` | The encoding to write the file in, such as `"ISO-8859-1"`. `nil` writes UTF-8, or the format's own encoding, such as ASCII for `:fixed`. Name the byte order of UTF-16 or UTF-32, such as `"UTF-16LE"`.
| `columns` | `nil` | Columns to include when rendering tabular output.
| `nils` | `false` | When `true`, store `nil` results too; when `false`, skip them.
### Multiple output files
A single batch job can write several output files by registering more than one output category and
returning categorized results from `perform`.
Use `RocketJob::Batch::Result` to direct a single value to a named category, and
`RocketJob::Batch::Results` to return several at once. `Result.new` takes the **category first, then
the value**:
~~~ruby
class MultiFileJob < RocketJob::Job
include RocketJob::Batch
self.destroy_on_complete = false
# Default :main output category, plus an :invalid category
output_category
output_category(name: :invalid)
def perform(line)
if line.length < 10
# Send short lines to the :invalid output collection
RocketJob::Batch::Result.new(:invalid, line)
else
# Plain return values go to the :main output collection
line.reverse
end
end
end
~~~
Download each category to its own file:
~~~ruby
job.download("reversed.txt.gz")
job.download("invalid.txt.gz", category: :invalid)
~~~
To write to several categories from a single `perform` call, collect them in a `Results`:
~~~ruby
def perform(row)
outputs = RocketJob::Batch::Results.new
outputs << {name: row["name"], age: row["age"]} # goes to :main
outputs << RocketJob::Batch::Result.new(:zip_codes, {zip: row["zip"]}) # goes to :zip_codes
outputs
end
~~~
## Reading tabular files
Received data is often tabular, like a spreadsheet, with a header row describing each column (CSV,
PSV, Excel, and so on). Set `format` on the `input_category` and Rocket Job parses each row just
before `perform` is called, passing in a `Hash` of header name to value instead of the raw line:
~~~ruby
class TabularJob < RocketJob::Job
include RocketJob::Batch
input_category format: :csv
def perform(record)
# record is a Hash, for example:
# { "first_field" => 100, "second" => 200, "third" => 300 }
end
end
~~~
~~~ruby
job = TabularJob.new
job.upload("my_really_big_csv_file.csv")
job.save!
~~~
CSV parsing is left to the workers, so the file still uploads a line at a time with minimal memory
overhead, even for very large files.
### Auto-detecting the file type
Set `format: :auto` to detect the format from the upload file name. The same unchanged job can then
process CSV, PSV, JSON, or xlsx files, as long as the column headers match:
~~~ruby
class TabularJob < RocketJob::Job
include RocketJob::Batch
input_category format: :auto
def perform(record)
# record is a Hash of header name => value
end
end
~~~
~~~ruby
TabularJob.new.tap { |j| j.upload("really_big.csv") }.save!
TabularJob.new.tap { |j| j.upload("really_big.xlsx") }.save!
TabularJob.new.tap { |j| j.upload("really_big.json") }.save!
~~~
### Validating columns
Set `allowed_columns` and `required_columns` on a tabular `input_category` to restrict the columns
it accepts. An unknown column raises `IOStreams::Errors::InvalidHeader`, unless `skip_unknown` is
true, in which case it is left out of every record. A missing required column always raises.
~~~ruby
input_category format: :csv,
allowed_columns: %w[login last_login name state],
required_columns: %w[login],
skip_unknown: true
~~~
The restrictions apply to every input:
* A header row is checked during upload, so a malformed file is rejected before any worker runs.
Column names are compared after cleansing, or as they are with `header_cleanser: :none`.
* Columns supplied with `columns`, in place of a header row, are checked during upload.
* A format without a header row, such as JSON, supplies the keys of each record, so they are
checked as each record is processed, and are cleansed like a header row. With `format: :auto`
the allow list therefore still applies when a `.csv` file is renamed to `.json`.
Set `IOStreams.enforce_column_restrictions = false` to apply them only to a cleansed header row, as
earlier versions did. IOStreams then logs a warning when applying them would change the input.
## Writing tabular files
To produce a tabular output file, set `format` on the `output_category` and return a `Hash` from
`perform`. Rocket Job renders each hash into a line of the chosen format, and writes the header row
automatically:
~~~ruby
class ExportUsersJob < RocketJob::Job
include RocketJob::Batch
# Only these columns are written, in this order
output_category format: :csv, columns: ["login", "last_login"]
def perform(id)
u = User.find(id)
{"login" => u.login, "last_login" => u.updated_at}
end
end
~~~
~~~ruby
job = ExportUsersJob.new
job.upload_arel(User.where(locked: true))
job.save!
# ... once complete ...
job.download("output.csv")
~~~
Sample `output.csv`:
~~~csv
login,last_login
jbloggs,2019-02-11 05:43:20
kadams,2019-01-12 01:20:20
~~~
### Filtering output columns
Rocket Job only writes the columns listed in `columns`, so `perform` can return a full attribute
hash and let the category select which columns to export. The same job can then export different
columns on different runs:
~~~ruby
class ExportUsersJob < RocketJob::Job
include RocketJob::Batch
output_category format: :csv, columns: ["login", "last_login"]
def perform(login)
# Return all attributes; only the configured columns are written
User.find_by(login: login).attributes
end
end
~~~
Override the columns per instance to widen or narrow the export:
~~~ruby
job = ExportUsersJob.new
job.output_category.columns = ["login", "last_login", "name", "state"]
job.save!
~~~
### Single output file via after_batch
The `after_batch` callback runs once, after all slices finish, which is a natural place to download
the assembled output file. This job parses a CSV input and writes a single CSV output:
~~~ruby
class TransformJob < RocketJob::Job
include RocketJob::Batch
self.destroy_on_complete = false
input_category format: :csv
output_category format: :csv
after_batch :download_file
def perform(row)
{
name: "#{row['first_name'].downcase} #{row['last_name'].downcase}",
age: row["age"]
}
end
def download_file
download("names.csv")
end
end
~~~
## Compression and encryption
Each category has a `serializer` that controls how its slices are stored. Compression reduces network
and disk usage, and is recommended for large jobs. As of Rocket Job v6 the default serializer is
`:compress`; set it to `:none` to disable. Encryption is opt-in and configured per job: setting the
serializer to `:encrypt` keeps that job's slices protected at rest, which helps meet compliance
requirements, without any change to your `#perform` code.
~~~ruby
class ReverseJob < RocketJob::Job
include RocketJob::Batch
input_category serializer: :compress
output_category serializer: :compress
def perform(line)
line.reverse
end
end
~~~
Set the serializer to `:encrypt` to encrypt slices at rest with
[Symmetric Encryption](https://encryption.reidmorrison.com). Data is compressed
before being encrypted, to reduce the volume encrypted:
~~~ruby
input_category serializer: :encrypt
output_category serializer: :encrypt
~~~
### Fast bzip2 output files
Compressing a large output file with bzip2 is slow, and `download` runs on a single thread, so
compressing the whole file as it is written can take longer than processing the job did. The `:bz2`
and `:encrypted_bz2` output serializers move that work to the workers instead:
* Each worker bzip2-compresses its own slice when it saves the output, so compression runs in
parallel across every worker processing the job.
* `download` does not decompress the slices and compress them again. It writes each slice's
compressed data directly to the output file. With `:encrypted_bz2` it only decrypts each slice
first; with `:bz2` it copies the slice as is.
`:encrypted_bz2` also keeps the output encrypted at rest in MongoDB, like `:encrypt`, until it is
downloaded. The downloaded file itself is bzip2 compressed, not encrypted.
~~~ruby
class ExportJob < RocketJob::Job
include RocketJob::Batch
self.destroy_on_complete = false
input_category format: :csv
output_category format: :csv, columns: %w[name age], serializer: :encrypted_bz2
after_batch :download_file
def perform(row)
{"name" => "#{row['first_name']} #{row['last_name']}", "age" => row["age"]}
end
def download_file
download("export.csv.bz2")
end
end
~~~
Things to know:
* The output file name must end in `.bz2`. `download` uses the file name to recognize that the
file is bzip2 compressed, and writes the already compressed slices into it.
* A header line, such as the CSV header row above, is compressed and written at the start of the file.
* The text is written in the output category's `encoding`, or the format's own, such as ASCII for
fixed width, since it is converted before it is compressed. A character that the encoding does not
have fails the slice when it is processed. An encoding cannot be set on the download path.
* The output file is a series of bzip2 streams, at least one per slice, which the bzip2 format allows. The
`bzip2` command line utility, and most tools built on libbzip2, read every stream. Some other
implementations stop after the first stream and return only the first slice, so check that the
system receiving the file reads multi-stream bzip2 files.
* Records are separated with a newline (`"\n"`); the record delimiter cannot be changed.
* The return value of `download` is the number of slices written, not the number of records.
* Downloading with a block yields the header line, if any, as text, followed by each slice's
compressed data rather than the individual records.
### PGP encrypted output files
When exchanging files with another system, an open standard like PGP is ideal. Because `download`
accepts an [IOStreams](https://iostreams.reidmorrison.com) path, the output file can be PGP
encrypted for a recipient on the way out:
~~~ruby
class ExportJob < RocketJob::Job
include RocketJob::Batch
self.destroy_on_complete = false
input_category format: :csv
output_category format: :csv
field :pgp_public_key, type: String
validates_presence_of :pgp_public_key
after_batch :download_file
def perform(row)
{name: "#{row['first_name']} #{row['last_name']}", age: row["age"]}
end
def download_file
path = IOStreams.path("names.csv")
path.option(:pgp, import_and_trust_key: pgp_public_key)
download(path)
end
end
~~~
## Throttling concurrent workers
`throttle_running_workers` limits how many workers process slices of a single batch job instance at
once. Use it when too many concurrent workers would overwhelm a third party system or write too much
data too quickly to a primary database. It also lets several batch jobs run concurrently rather than
one job consuming every worker.
~~~ruby
class ReverseJob < RocketJob::Job
include RocketJob::Batch
# No more than 10 workers on this job at a time
self.throttle_running_workers = 10
def perform(line)
line.reverse
end
end
~~~
This value can be changed at any time, even while the job runs, to raise or lower the worker count.
It is a soft limit: the number of active workers may briefly exceed or dip below it. `0` or `nil`
means no limit (the default).
### Custom batch throttles
Define custom throttles for batch jobs with `define_batch_throttle`. The named method receives the
slice and returns true when the throttle is exceeded, in which case the slice is left for later:
~~~ruby
class MyJob < RocketJob::Job
include RocketJob::Batch
# Do not process slices when the MySQL replica delay exceeds 5 minutes
define_batch_throttle :mysql_throttle_exceeded?
def perform(record)
# ...
end
private
def mysql_throttle_exceeded?(slice)
status = ActiveRecord::Base.connection.select_one("show slave status")
seconds_delay = Hash(status)["Seconds_Behind_Master"].to_i
seconds_delay >= 300
end
end
~~~
As with simple jobs, pass a `description:` (a String, or a Proc receiving the job and slice) to set
the reason shown in Mission Control while slices are throttled. It is recorded on the job in
`throttled_by` and cleared once slices resume processing.
### Processing windows
`RocketJob::Batch::ThrottleWindows` restricts when slices may be processed, which is useful for a
long-running job that should only run outside business hours. It supports up to two windows. The
windows only gate slice processing; the job can still start and finish at any time.
~~~ruby
class AfterHoursJob < RocketJob::Job
include RocketJob::Batch
include RocketJob::Batch::ThrottleWindows
# Monday to Thursday, slices may run from 5pm Eastern for 15 hours (until 8am)
self.primary_schedule = "0 17 * * 1-4 America/New_York"
self.primary_duration = 15.hours
# All weekend, starting Friday 5pm Eastern for 63 hours (until 8am Monday)
self.secondary_schedule = "0 17 * * 5 America/New_York"
self.secondary_duration = 63.hours
def perform(record)
# ...
end
end
~~~
### Lowering priority for large jobs
`RocketJob::Batch::LowerPriority` automatically lowers a job's priority based on its `record_count`,
so that large jobs yield to smaller ones. Add `:lower_priority` as a `before_batch`, after the
`record_count` has been set (that is, after the data has been uploaded):
~~~ruby
class SampleJob < RocketJob::Job
include RocketJob::Batch
include RocketJob::Batch::LowerPriority
before_batch :upload_data, :lower_priority
def perform(record)
record.reverse
end
private
def upload_data
upload { |stream| %w[abc def ghi].each { |r| stream << r } }
end
end
~~~
## Error handling
Because a batch job is made of many slices, individual records can fail while others keep processing.
Inspect the exceptions on failed slices:
~~~ruby
job = RocketJob::Job.find("55bbce6b498e76424fa103e8")
job.input.each_failed_record do |record, slice|
p slice.exception
end
~~~
Once every slice has either completed or failed, and only failed slices remain, the job as a whole is
marked `failed`. Retrying the job retries only the failed slices, so successfully processed records
are not reprocessed.
## Inspecting slices from the console
The slices that make up a batch job are ordinary MongoDB documents, so a running or failed job can be
inspected directly from a Rails (or `irb`) console. `job.input` returns the input slice collection and
`job.output` (when the job collects output) returns the output slice collection. Both respond to the
same set of query and enumeration methods.
**Counting slices.** `count` returns the total number of slices, and each state has its own scope
(`queued`, `running`, `failed`, `completed`) that can be counted or iterated:
~~~ruby
job = RocketJob::Job.find("55bbce6b498e76424fa103e8")
job.input.count # Total number of input slices
job.input.failed.count # Number of failed slices
job.input.running.count # Slices currently being processed
job.input.queued.count # Slices still waiting to be processed
~~~
**Fetching slices.** The state scopes, together with `first`, `last`, `each`, `where`, and the standard
`Enumerable` methods, return individual slices. `first`/`last` are sorted by `_id`, which is usually the
order in which the data was uploaded:
~~~ruby
job.input.failed.first # First failed slice
job.input.first # First input slice, in upload order
# Iterate over every failed slice and print its exception class:
job.input.failed.each { |slice| puts slice.exception.class_name }
~~~
**Reading records within a slice.** A slice behaves like an array of its records, and carries metadata
about how it was processed:
~~~ruby
slice = job.input.failed.first
slice.records # Array of records in this slice
slice.size # Number of records in the slice
slice.first_record_number # Line number of the first record in the original upload
slice.failure_count # How many times this slice has failed
slice.worker_name # Worker that last processed the slice
slice.failed_record # The specific record that raised the exception
~~~
**Inspecting the exception.** A failed slice embeds a `RocketJob::JobException` on `slice.exception`
exposing `class_name`, `message`, `backtrace`, and `worker_name`:
~~~ruby
exception = job.input.failed.first.exception
exception.class_name # e.g. "RuntimeError"
exception.message
exception.backtrace
~~~
**Summarizing failures.** For a large job with many failed slices, `group_exceptions` aggregates the
failures by exception class, returning the count and the unique messages for each class. This is the
fastest way to see _what_ is failing without paging through slices one at a time:
~~~ruby
job.input.group_exceptions.each do |summary|
puts "#{summary.class_name}: #{summary.count}"
summary.messages.each { |message| puts " #{message}" }
end
~~~
All of the above work equally on `job.output` for jobs that collect output, and on named categories via
`job.input(:category_name)` / `job.output(:category_name)`.
## Editing and retrying failed records
Sometimes a slice fails because of bad data rather than a code bug. Rather than fixing the source file
and re-uploading the whole job, the offending record can be corrected directly on the slice and the job
retried. A slice behaves like a plain `Array` of records via `records`, and saving the slice persists the
edited records.
**Example: correct the failed record and retry the job.**
`failed_record` returns the record that raised the exception, and `processing_record_number` is its
(1-based) position within the slice:
~~~ruby
job = RocketJob::Job.find("55bbce6b498e76424fa103e8")
slice = job.input.failed.first
slice.failed_record # => "12345,,Jack" (missing middle field)
# Edit the record in place. `records` is a regular Array.
index = slice.processing_record_number - 1
slice.records[index] = "12345,A,Jack"
slice.save!
# Retry the job: every failed slice is requeued and reprocessed.
job.retry!
~~~
On retry each slice resumes from `processing_record_number`, so records that already completed
successfully within the slice are not reprocessed. The corrected record is the next one processed.
**Example: fix every record in a slice.**
Any change to the `records` array is persisted by `save!`:
~~~ruby
slice = job.input.failed.first
slice.records = slice.records.map(&:strip) # Clean up all records in the slice
slice.save!
job.retry!
~~~
**Example: retry a single slice that failed while the job is still running.**
While a job is still `running` (some slices failed but others are still processing), an individual slice
can be edited and requeued on its own without retrying the whole job. An active worker picks it up:
~~~ruby
slice = job.input.failed.first
slice.records[0] = "corrected value"
slice.save!
slice.retry! # Move just this slice from failed back to queued
~~~
Note that workers only process slices for a job that is in the `running` state. Once all slices have
finished and only failed slices remain, the job itself transitions to `failed`, and `slice.retry!`
alone will not reprocess it. In that case use `job.retry!`, which returns the job to `running` and
requeues all of its failed slices.
## Batch callbacks
In addition to the standard [job callbacks](guide.html#callbacks), batch jobs add callbacks at the
slice and batch level:
* `before_slice`, `after_slice`, `around_slice`: run on the worker, around each slice.
* `before_batch`, `after_batch`: run once for the whole job. They run asynchronously. `around_batch`
is not supported.
`before_batch` is the place to upload data, and `after_batch` the place to download results or do
final bookkeeping, as shown in the [single output file](#single-output-file-via-after_batch) and
[lower priority](#lowering-priority-for-large-jobs) examples.
## Gathering statistics
`RocketJob::Batch::Statistics` lets a job count things while it runs and have those counts aggregated
across every slice and worker. It is the standard way to answer "how many records were valid, invalid,
or skipped?" without adding your own fields or a separate datastore.
Add the plugin and call `statistics_inc` inside `perform`:
~~~ruby
class ImportJob < RocketJob::Job
include RocketJob::Batch
include RocketJob::Batch::Statistics
def perform(row)
if row["email"].blank?
statistics_inc("invalid")
return
end
statistics_inc("imported")
# ... import the row ...
end
end
~~~
When the job completes, the totals are available in the `statistics` hash field:
~~~ruby
job.reload.statistics
# => {"imported" => 9_840, "invalid" => 160}
~~~
The counts are also included in the job's log entry when it completes or fails.
Increment by more than one by passing an amount, and increment several counters at once by passing a
hash:
~~~ruby
statistics_inc("rows", row.size)
statistics_inc("invalid" => 1, "skipped" => 1)
~~~
Keys may use dot notation to build nested counts, which is handy for grouping related categories:
~~~ruby
statistics_inc("invalid.missing_email")
statistics_inc("invalid.bad_country")
# => {"invalid" => {"missing_email" => 12, "bad_country" => 4}}
~~~
Statistics are committed per slice using an atomic MongoDB `$inc`, so thousands of workers can update
the same counters concurrently. Counts are gathered while a slice is processed and only saved for
records that complete successfully: if a `perform` raises an exception, the increments from that record
are discarded, so retrying a failed slice does not double-count.
The built-in [`OnDemandBatchJob`](jobs.html#on-demand-batch-job) already includes this plugin, so
`statistics_inc` is available in its `code` without any extra setup.
## Batch fields and status
Including `RocketJob::Batch` adds these fields:
| Field | Description
|:---------------|:------------
| `record_count` | Total number of input records. Set automatically by `upload`. Until it is set, workers process slices but do not complete the job, which allows processing to begin while data is still uploading.
| `sub_state` | Read-only. Breaks the `running` state into `:before`, `:processing`, `:after`, and `:complete`.
`percent_complete`, `worker_count`, and `worker_names` are all batch-aware. The `status` hash adds
slice-level counts (`queued_slices`, `active_slices`, `failed_slices`, `output_slices`) and, while
running, an estimated remaining duration:
~~~ruby
job.reload
job.status
# => {"active_slices" => 8, "failed_slices" => 0, "queued_slices" => 1200, ... }
~~~
## The batch job lifecycle
A batch job uses the same top-level states as a [simple job](guide.html#the-job-lifecycle)
(`queued`, `running`, `completed`, `failed`, `paused`, `aborted`), but the `running` state is broken
into `sub_state` phases so that the one-time `before_batch` / `after_batch` work is coordinated
separately from the many slices processed in parallel:
~~~mermaid
stateDiagram-v2
[*] --> queued : create / upload
queued --> running : start
state running {
[*] --> before : sub_state
before --> processing : before_batch done
processing --> after : all slices done
after --> [*]
}
running --> completed : complete
completed --> [*]
running --> failed : a slice (or callback) fails
failed --> queued : retry (was in before_batch)
failed --> running : retry (re-run failed slices / after_batch)
queued --> paused : pause
running --> paused : pause (only during processing)
paused --> running : resume
running --> queued : requeue (worker died, in before_batch)
running --> running : requeue (worker died, processing / after_batch)
queued --> aborted : abort
running --> aborted : abort
failed --> aborted : abort
paused --> aborted : abort
aborted --> [*]
~~~
The three `running` sub-states, exposed on the read-only `sub_state` field:
* **`before`**: the job has started and its `before_batch` callbacks are running on a single worker.
This is where input is typically uploaded.
* **`processing`**: slices are being claimed and processed concurrently by many workers. This is the
only sub-state in which a batch job is [pausable](#throttling-concurrent-workers).
* **`after`**: every slice has finished, and the `after_batch` callbacks are running on a single
worker (downloading results, final bookkeeping). `complete` then clears `sub_state` and moves the
job to `completed`.
How batch jobs differ from simple jobs in this diagram:
* **`fail`**: if any slice raises and only failed slices remain, the job as a whole becomes `failed`
(see [Error handling](#error-handling)). Individual slices carry their own state and exceptions.
* **`retry`** is sub-state aware: a job that failed during `before_batch` retries back to `queued`,
while one that failed during or after processing retries straight to `running` and reprocesses only
the failed slices, leaving already-completed records untouched.
* **`requeue`** (automatic when a worker's server dies) also depends on sub-state: work interrupted
during `before_batch` goes back to `queued`; work interrupted during processing or `after_batch` is
requeued within `running` so the running slices are reclaimed by other workers.
As with simple jobs, each transition is callable on the job and comes in two forms: `job.abort`
changes the state in memory only (call `job.save!` to persist), while `job.abort!` transitions and
saves in one step. See [Triggering a transition](guide.html#triggering-a-transition).
## How batch jobs work
A batch job's input is uploaded into a MongoDB collection dedicated to that job and split into
slices. Each slice is an independent unit of work that any worker can claim with an atomic operation,
so thousands of workers across many servers process slices concurrently without colliding:
~~~mermaid
flowchart LR
input["input file"] --> slices["slices"]
slices --> worker1["worker"]
slices --> worker2["worker"]
slices --> workerN["worker"]
worker1 -- slice 1 --> output["output collection"]
worker2 -- slice 2 --> output
workerN -- slice N --> output
output --> download["download"]
~~~
Slices live in a separate MongoDB client (`rocketjob_slices`) from the jobs themselves. MongoDB's
ability to spill from memory to disk is what lets a single job hold millions of input and output
records without exhausting memory or needing a separate data store. Each slice carries its own state,
so a failure is isolated to that slice, retains its exception, and can be retried on its own.
## Next steps
* [Programmer's Guide](guide.html): the core job API that batch jobs build on.
* [Dirmon](dirmon.html): trigger batch jobs automatically when files arrive.
* [Mission Control](mission_control.html): watch slices and jobs run, and retry, pause, or abort them.
* [Included Jobs](jobs.html): ready-to-use jobs such as `OnDemandBatchJob`.
---
## Included Jobs
Rocket Job ships with a set of ready-to-run jobs for common tasks: cleaning out old jobs, monitoring
directories for new files, copying and converting files, running ad-hoc Ruby code, and re-encrypting
data. They all live under the `RocketJob::Jobs` namespace and are themselves ordinary jobs, so they
can be scheduled, prioritized, retried, and managed through
[Mission Control](mission_control.html) like any other job.
This page covers each one, what it does, and how to create it. For the underlying concepts (fields,
state machine, scheduling, retries) see the [Programmer's Guide](guide.html); for parallel file
processing see the [Batch Guide](batch.html).
## Housekeeping Job
`RocketJob::Jobs::HousekeepingJob` removes old jobs so they do not accumulate and consume MongoDB
storage. This matters most for jobs that set `self.destroy_on_complete = false` (so they remain after
finishing) and for failed or aborted jobs, which are never destroyed automatically.
Retention is configured separately per state, so for example completed jobs can be cleaned up sooner
than failed jobs that may still need investigation. A retention of `nil` means "keep forever".
| State | Default retention |
|:----------|:------------------|
| Aborted | 7 days |
| Completed | 7 days |
| Failed | 14 days |
| Paused | never (`nil`) |
| Queued | never (`nil`) |
The job uses the [Cron](guide.html#scheduled-jobs) plugin and runs every 15 minutes. It is also a
singleton: only one instance can be queued or running at a time.
Create it with the defaults:
~~~ruby
RocketJob::Jobs::HousekeepingJob.create!
~~~
Create it with the default values shown explicitly, so they can be adjusted:
~~~ruby
RocketJob::Jobs::HousekeepingJob.create!(
aborted_retention: 7.days,
completed_retention: 7.days,
failed_retention: 14.days,
paused_retention: nil,
queued_retention: nil
)
~~~
Remove aborted jobs after 1 day, completed jobs after 30 minutes, and never remove failed jobs:
~~~ruby
RocketJob::Jobs::HousekeepingJob.create!(
aborted_retention: 1.day,
completed_retention: 30.minutes,
failed_retention: nil
)
~~~
In addition to removing old jobs, the housekeeping job cleans up after servers that have died without
shutting down cleanly. When `destroy_zombies` is `true` (the default) it destroys zombie `Server`
records and requeues any jobs whose worker disappeared along with its server, so that work is not lost.
Set `destroy_zombies: false` to disable this.
~~~ruby
RocketJob::Jobs::HousekeepingJob.create!(destroy_zombies: false)
~~~
## Dirmon Job
`RocketJob::Jobs::DirmonJob` (Directory Monitor) watches one or more directories for new files and
starts a job to process each file as it arrives. It scans every 5 minutes by default, waits for each
file to stop growing before acting on it (so partially-uploaded files are not processed), and archives
files once handled.
Dirmon is driven by `RocketJob::DirmonEntry` records that describe what to watch and which job to
start. Because directory monitoring is a feature in its own right, with its own Mission Control
screens, it has a dedicated page: see the [Directory Monitoring guide](dirmon.html) for the full story.
Start Dirmon for the first time:
~~~ruby
RocketJob::Jobs::DirmonJob.create!
~~~
Dirmon is a singleton, so if an instance is already queued or running, `create!` raises:
~~~
Validation failed: State Another instance of this job is already queued or running
~~~
Use `create` (without the bang) to start it only if one is not already present:
~~~ruby
RocketJob::Jobs::DirmonJob.create
~~~
Change the scan interval by supplying a `cron_schedule`. To scan every minute instead of every 5:
~~~ruby
RocketJob::Jobs::DirmonJob.create!(cron_schedule: "*/1 * * * * UTC")
~~~
## Conversion Job
`RocketJob::Jobs::ConversionJob` converts a file from one tabular format to another: CSV, JSON, PSV,
and xlsx. It is a [batch](batch.html) job, so even very large files are converted in parallel across
workers. Compression and archive formats (`.gz`, `.zip`, and so on) are detected automatically from
the file name, and the source can be a local path or a remote URL.
Both the input and output categories use `format: :auto`, which infers the format from each file's
extension.
Convert a CSV file to JSON:
~~~ruby
job = RocketJob::Jobs::ConversionJob.new
job.input_category.file_name = "data.csv"
job.output_category.file_name = "data.json"
job.save!
~~~
Convert JSON to PSV and compress the output with GZip:
~~~ruby
job = RocketJob::Jobs::ConversionJob.new
job.input_category.file_name = "data.json"
job.output_category.file_name = "data.psv.gz"
job.save!
~~~
Read a zipped CSV file from a remote website and write a GZipped JSON file:
~~~ruby
job = RocketJob::Jobs::ConversionJob.new
job.input_category.file_name = "https://example.org/file.zip"
job.output_category.file_name = "data.json.gz"
job.save!
~~~
Convert a CSV file that Excel saved on Windows, in Windows-1252, to JSON, which is written in UTF-8.
The `encoding` of the output category writes the output file in another encoding the same way:
~~~ruby
job = RocketJob::Jobs::ConversionJob.new
job.input_category.file_name = "legacy.csv"
job.input_category.encoding = "Windows-1252"
job.output_category.file_name = "data.json"
job.save!
~~~
## Copy File Job
`RocketJob::Jobs::CopyFileJob` copies a file from a source to a target, where each can be a local path,
a URL, or any location supported by [IOStreams](https://iostreams.reidmorrison.com) (SFTP, S3,
HTTP, and more). It is commonly used to push a finished output file to an SFTP server or object store.
Because it includes the [Retry](guide.html#automatic-retry) plugin, a failed copy is retried
automatically up to 10 times, which is useful given that remote transfers are prone to transient
failures.
Upload a file to an SFTP server:
~~~ruby
RocketJob::Jobs::CopyFileJob.create!(
source_url: "/exports/uploads/important.csv.pgp",
target_url: "sftp://sftp.example.org/uploads/important.csv.pgp",
target_args: {
username: "Jack",
password: "OpenSesame",
ssh_options: {
IdentityFile: "~/.ssh/secondary"
}
}
)
~~~
The `source_streams` and `target_streams` options apply IOStreams transformations (such as
compression or encryption) on the way through, and `source_args` / `target_args` pass options to the
underlying source and target. When the Symmetric Encryption gem is installed, any argument whose key
starts with `encrypted_` is decrypted before use, and any whose key starts with `secret_config_` is
looked up via [Secret Config](https://config.reidmorrison.com); the connection password is also stored
encrypted.
A file is copied byte for byte, unless `source_encoding` or `target_encoding` is set, which converts
its text from the encoding of the source to that of the target. When only one is set, the other is
UTF-8. The text is read and written through the streams that the file names select, unless
`source_streams` or `target_streams` is set, so a `.gz` source is decompressed before its text is
converted. For example, to send a file that Excel saved in Windows-1252 to a partner who requires UTF-8:
~~~ruby
RocketJob::Jobs::CopyFileJob.create!(
source_url: "/exports/prices.csv",
source_encoding: "Windows-1252",
target_url: "sftp://sftp.example.org/uploads/prices.csv"
)
~~~
Instead of a `source_url`, raw data can be supplied directly with `source_data` (limited to about
15 MB after compression):
~~~ruby
RocketJob::Jobs::CopyFileJob.create!(
source_data: "id,name\n1,Jack\n",
target_url: "s3://example-bucket/people.csv"
)
~~~
## Upload File Job
`RocketJob::Jobs::UploadFileJob` uploads a single file into another job and then starts that job. It is
the mechanism [Dirmon](dirmon.html) uses to feed an arriving file into the job that should process it,
but it can be used directly with any job class.
The target job must be a `RocketJob::Job` and must accept the file in one of three ways: by
implementing `#upload` (the usual case for batch jobs), or by having an `upload_file_name` or
`full_file_name` field that the path is assigned to.
~~~ruby
RocketJob::Jobs::UploadFileJob.create!(
job_class_name: "MyProcessFileJob",
upload_file_name: "/incoming/orders.csv",
properties: {description: "Orders for today"}
)
~~~
`properties` is a hash of fields to set on the created job; each key must correspond to a writable
field on that job class, or validation fails. `original_file_name` can be supplied so the job sees the
original name (and its file extension, which drives format detection) even when the path on disk is a
temporary name. If anything goes wrong during the upload, the partially-populated downstream job is
cleaned up so no half-uploaded job is left behind.
## On Demand Job
`RocketJob::Jobs::OnDemandJob` runs a snippet of Ruby supplied as a string at create time, without
having to write and deploy a dedicated job class. It is ideal for one-off fixes, data cleanups, and
maintenance tasks that should run through the same queue, scheduling, and Mission Control machinery as
everything else.
The `code` field holds the Ruby to run; it is compiled into the job's `perform` method and validated
when the job is saved, so a syntax error is caught immediately rather than at run time. The job keeps
itself after completion (`destroy_on_complete = false`), and it includes the
[Cron](guide.html#scheduled-jobs) and [Retry](guide.html#automatic-retry) plugins.
Run some code once:
~~~ruby
code = <<~CODE
User.unscoped.order("updated_at DESC").each do |user|
user.cleanse_attributes!
user.save!
end
CODE
RocketJob::Jobs::OnDemandJob.create!(
code: code,
description: "Cleanse users"
)
~~~
Test the code inline in a console before queuing it:
~~~ruby
job = RocketJob::Jobs::OnDemandJob.new(code: code, description: "cleanse users")
job.perform_now
~~~
Pass input data, available inside the code as the `data` hash. Use string keys only, not symbols:
~~~ruby
code = <<~CODE
puts data["a"] * data["b"]
CODE
RocketJob::Jobs::OnDemandJob.create!(
code: code,
data: {"a" => 10, "b" => 2}
)
~~~
Retain a result by writing it back into `data`, which is persisted on the job:
~~~ruby
code = <<~CODE
data["result"] = data["a"] * data["b"]
CODE
RocketJob::Jobs::OnDemandJob.create!(
code: code,
data: {"a" => 10, "b" => 2}
)
~~~
Schedule it to run nightly at 2am Eastern:
~~~ruby
RocketJob::Jobs::OnDemandJob.create!(
cron_schedule: "0 2 * * * America/New_York",
code: code
)
~~~
Change the priority, description, or retry behavior like any other job:
~~~ruby
RocketJob::Jobs::OnDemandJob.create!(
code: code,
description: "Cleanse users",
priority: 30,
retry_limit: 5
)
~~~
## On Demand Batch Job
`RocketJob::Jobs::OnDemandBatchJob` is the [batch](batch.html) counterpart to the On Demand Job: the
supplied `code` runs once per record, in parallel across workers. It is the standard tool for data
correction or cleansing over a large set of rows.
The `code` field is compiled into `perform(row)` and runs for every record. Optional `before_code` and
`after_code` fields run once, before and after the batch, and are typically used to upload the records
to process. As with `OnDemandJob`, all of the code is validated when the job is saved.
Upload an Active Record relation and process each row by its id. Uploading a relation automatically
sets `record_count`:
~~~ruby
code = <<~CODE
if user = User.find(row)
user.cleanse_attributes!
user.save(validate: false)
end
CODE
job = RocketJob::Jobs::OnDemandBatchJob.new(code: code, description: "cleanse users")
job.upload(User.unscoped.order("updated_at DESC"))
job.save!
~~~
Test against a subset directly in a console, then clean up the temporary slice collection:
~~~ruby
job = RocketJob::Jobs::OnDemandBatchJob.new(code: code, description: "cleanse users")
job.upload(User.unscoped.order("updated_at DESC").limit(100))
job.perform_now
job.cleanup!
~~~
Output is not collected by default. Call `#collect_output` to keep it, and set batch options such as
the [worker throttle](batch.html#throttling-concurrent-workers) and priority:
~~~ruby
job = RocketJob::Jobs::OnDemandBatchJob.new(
description: "Fix data",
code: code,
throttle_running_workers: 5,
priority: 30
)
job.collect_output
job.save!
~~~
Move the upload into `before_code` so the whole job, including how it loads its records, is described
in one `create!`:
~~~ruby
before_code = <<~CODE
upload(User.unscoped.order("updated_at DESC"))
CODE
code = <<~CODE
if user = User.find(row)
user.cleanse_attributes!
user.save(validate: false)
end
CODE
RocketJob::Jobs::OnDemandBatchJob.create!(
before_code: before_code,
code: code,
description: "cleanse users"
)
~~~
`OnDemandBatchJob` also mixes in [Batch::Statistics](batch.html#gathering-statistics), so counters incremented in
the code are aggregated and visible on the completed job.
## Re-Encrypt Job
`RocketJob::Jobs::ReEncrypt::RelationalJob` re-encrypts every `encrypted_` column in a relational
database, rotating data to the current
[Symmetric Encryption](https://encryption.reidmorrison.com) key. It is a batch job
that works directly against table and column names rather than models, so it covers tables whose
models have been removed and picks up new `encrypted_` columns automatically.
It is only defined when both Active Record and the `sync_attr` gem are available. Calling `start`
inspects the schema and queues one job per table that has encrypted columns:
~~~ruby
RocketJob::Jobs::ReEncrypt::RelationalJob.start
~~~
Because it discovers columns by name, any table with an `encrypted_` column is processed, including
temporary or non-application tables. Each table is processed in id ranges, and only values that change
under the new key are written back.
## Internal and testing jobs
A few jobs ship with Rocket Job for internal use and benchmarking rather than for direct use in an
application:
* `RocketJob::Jobs::ActiveJob` wraps an Active Job so it can run on Rocket Job through the Active Job
adapter. It is not created directly.
* `RocketJob::Jobs::SimpleJob` and `RocketJob::Jobs::PerformanceJob` are no-op jobs (simple and batch,
respectively) used to benchmark throughput. They are driven by `bin/rocketjob_perf` and
`bin/rocketjob_batch_perf`.
---
## Directory Monitoring
Watching a directory for new files and kicking off a job to process each one is one of the most
common tasks in any batch processing system. Almost every team ends up writing it themselves, along
with all the awkward parts: detecting when a file has finished uploading, archiving it so it is not
picked up twice, retrying after failures, and securing which directories may be read.
Rocket Job ships this as a built-in feature called **Dirmon** (Directory Monitor). Because it is part
of Rocket Job it also comes with a full management screen in
[Rocket Job Mission Control](mission_control.html), the web UI, so files, schedules, and failures can
be managed without writing or deploying any code.
Dirmon is driven by two pieces:
* `RocketJob::Jobs::DirmonJob` is a scheduled job that scans the configured directories on a fixed
interval (every 5 minutes by default).
* `RocketJob::DirmonEntry` is a persisted record describing *one* thing to watch: a path pattern, the
job class to start, where to archive processed files, and any fields to set on that job.
The key idea is that **a `DirmonEntry` can populate the fields of the job it starts**. A new file is
not just handed to a job: the entry decides which job class runs and pre-sets its fields. That is what
makes Dirmon able to launch any user-defined or built-in job, fully configured, for each incoming
file.
## Why per-entry job fields matter
A very common deployment looks like this: customers upload files over SFTP, each into their own
account-specific directory. The files all need the same processing, but the job needs to know *which
account* a file belongs to, and often a few other details such as an email address to notify when the
output is ready for pickup.
With Dirmon this is solved by creating one `DirmonEntry` per account. Each entry watches that account's
directory and sets the account-specific fields on the job through its `properties` hash:
~~~ruby
class CustomerImportJob < RocketJob::Job
include RocketJob::Batch
# Keep the job after completion so the output file can be downloaded.
self.destroy_on_complete = false
# Account that owns this file. Set per DirmonEntry.
# `user_editable: true` also makes it editable in Mission Control.
field :account_id, type: Integer, user_editable: true
# Where to send the "your file is ready" notification.
field :notify_email, type: String, user_editable: true
input_category serializer: :encrypt
output_category
after_batch :notify_when_ready
# Called once per record, spread across all available workers.
def perform(row)
Importer.new(account_id: account_id).transform(row)
end
private
def notify_when_ready
CustomerMailer.import_complete(notify_email, id).deliver_later if notify_email
end
end
~~~
Create one entry per account, each setting the fields specific to that account:
~~~ruby
RocketJob::DirmonEntry.create!(
name: "ACME customer imports",
pattern: "/var/sftp/acme/incoming/*.csv",
job_class_name: "CustomerImportJob",
archive_directory: "/var/sftp/acme/archive",
properties: {
account_id: 42,
notify_email: "ops@acme.example.com",
priority: 25
}
).enable!
RocketJob::DirmonEntry.create!(
name: "Globex customer imports",
pattern: "/var/sftp/globex/incoming/*.csv",
job_class_name: "CustomerImportJob",
archive_directory: "/var/sftp/globex/archive",
properties: {
account_id: 77,
notify_email: "files@globex.example.com"
}
).enable!
~~~
Now any file dropped into `/var/sftp/acme/incoming` starts a `CustomerImportJob` with `account_id`
`42` and the ACME notification address, while files for Globex start the same job scoped to their own
account. The processing code is written once; the per-account context comes from the entry.
The `properties` hash can set **any field on the target job that has a writer**, including the
built-in fields such as `priority`, `description`, and `run_at`, as well as the batch
`input_categories` / `output_categories`. Setting a value for a field the job does not define is
rejected by validation, so a typo fails fast when the entry is saved rather than silently doing
nothing.
For example, when one partner sends files in Windows-1252, set the `encoding` of the input category
for that partner's entry only, and the job converts its files to UTF-8:
~~~ruby
properties: {
input_categories: [{name: "main", encoding: "Windows-1252"}]
}
~~~
> Fields that should also be editable from the Mission Control web UI must be declared with
> `user_editable: true`, as shown above. Setting `properties` programmatically does not require it.
## How a scan works
`DirmonJob` does not start a job the instant a file appears, because the file may still be uploading.
Instead it waits for the file to stabilize:
1. On each run it lists the files matching every enabled entry's `pattern`.
2. A newly seen file's size is recorded and carried forward to the next run.
3. On the next run, if the file's size is unchanged, it is considered complete and its job is started.
If the size changed, it is recorded again and rechecked on the following run.
This means a file is normally picked up one scan interval after it finishes uploading. Object stores
are a special case: on stores where partial files are not visible until the upload completes (such as
Amazon S3), the file is processed on the first scan that sees it, with no stabilization wait.
When a file is ready, Dirmon archives it first and then starts the job, so the same file can never be
picked up twice (see [Archiving](#archiving)).
A file that is removed after a scan finds it, for example by another process, is skipped with a log
message, whichever storage it is on, rather than failing its entry.
## Creating a DirmonEntry
~~~ruby
entry = RocketJob::DirmonEntry.create!(
name: "Daily price feed",
pattern: "/data/prices/*.csv",
job_class_name: "PriceFeedJob",
archive_directory: "/data/prices/archive",
properties: { priority: 30 }
)
~~~
The fields of `DirmonEntry`:
* **`pattern`** (required, String)
A path glob used to find files. Standard `Dir.glob` wildcards apply, evaluated through
[IOStreams](https://iostreams.reidmorrison.com) so local paths and remote paths (SFTP, S3,
and so on) are supported. Examples:
* `input_files/process1/*.csv`
* `input_files/process2/**/*` (all files, recursively)
* `input_files/process2/*.{csv,txt}` (multiple extensions)
If the pattern contains no `*`, it is treated as an exact file name. Patterns are unique across all
entries, which helps prevent two entries from claiming the same files.
* **`job_class_name`** (required, String)
Name of the job class to start for each matching file. The class must be defined and inherit from
`RocketJob::Job`.
* **`archive_directory`** (required, String, defaults to `archive`)
Where matching files are moved before their job is started. See [Archiving](#archiving).
* **`properties`** (Hash, defaults to `{}`)
Fields to set on the job that is started, as described in
[Why per-entry job fields matter](#why-per-entry-job-fields-matter).
* **`name`** (String, optional but recommended)
A human-readable label used to identify the entry in Mission Control. Names must be unique.
## Enabling and disabling entries
A new `DirmonEntry` starts in the `pending` state and is **not** scanned until it is enabled. This is
deliberate: an entry can be reviewed before it goes live.
~~~ruby
entry.enable! # pending/disabled/failed -> enabled
entry.disable! # enabled/failed -> disabled
~~~
The states are:
* **`pending`** – newly created, not yet scanned.
* **`enabled`** – actively scanned by `DirmonJob`.
* **`disabled`** – manually paused.
* **`failed`** – an error occurred while processing the entry (for example a security violation or an
unreadable path), or its storage has been unavailable for too long (see
[High availability](#high-availability)). The entry is removed from scanning until it is
re-enabled. The cause is stored in the entry's embedded `exception`.
A snapshot of how many entries are in each state:
~~~ruby
RocketJob::DirmonEntry.counts_by_state
# => { pending: 1, enabled: 37, disabled: 3, failed: 1 }
~~~
## How the file reaches the job
When a file stabilizes, Dirmon archives it and enqueues a `RocketJob::Jobs::UploadFileJob`, which
builds the target job from the entry's `properties` and then hands the archived file to it. How the
file is delivered depends on what the job supports:
* **Batch jobs** (`include RocketJob::Batch`) implement `#upload`, so the file's contents are uploaded
directly into the job's input, split into slices, and processed in parallel. This is the usual case
for file processing.
* **Simple jobs** can instead declare an `upload_file_name` or `full_file_name` field; the absolute
path of the archived file is assigned to it, leaving the job to open and read the file itself.
A job that is neither a batch job nor declares one of those fields cannot be used as a Dirmon target
and is rejected by validation.
## Archiving
Before a job is started, the file is **moved** to the entry's `archive_directory`. Moving first
guarantees the file is out of the watched path before processing begins, so it cannot be discovered
again on a later scan. The archived file name is prefixed with the downstream job's id, which ties the
stored file to the job that processed it.
* If `archive_directory` is an **absolute** path, files are moved there directly.
* If it is a **relative** path, it is resolved relative to the directory the file was found in, and any
sub-directory structure under the pattern is preserved.
* If left unset it defaults to a directory named `archive`.
The file must be in a directory that the Dirmon process can write to, since moving a file changes its
directory. A file in a directory that cannot be written to is skipped, with a warning.
A file's name can hold any characters, including a name that is not valid UTF-8, such as `café.csv` written
in Latin-1 by a Windows program to a Linux file system. MongoDB only stores UTF-8, so such a file is archived
under its name with each byte that is not valid UTF-8 replaced by `�` (U+FFFD), such as
`_caf�.csv`. The upload job's original file name, and its description, show each such byte as
`\xHH`, such as `caf\xE9.csv`.
## Security: restricting which paths may be read
A `pattern` can point anywhere the process user can read, so Dirmon supports an allow-list of root
paths. When any paths are registered, every resolved file must live under one of them or it is skipped
and a warning is logged.
~~~ruby
# In an initializer, not via the web UI, so it cannot be tampered with.
RocketJob::DirmonEntry.add_whitelist_path("/var/sftp")
RocketJob::DirmonEntry.get_whitelist_paths
# => ["/var/sftp"]
RocketJob::DirmonEntry.delete_whitelist_path("/var/sftp")
~~~
Notes:
* If no paths are registered, the check is skipped entirely.
* Registering a path confirms it exists (`realpath` is resolved), and raises
`IOStreams::Errors::NotFound` when it does not, so absolute paths are recommended. Relative paths
are accepted but are not considered safe, since they can be manipulated.
* These should be set in application code (an initializer), not made editable in the web UI.
## Starting the directory monitor
Dirmon scanning is itself a scheduled Rocket Job, so it must be started once per installation:
~~~ruby
RocketJob::Jobs::DirmonJob.create!
~~~
`DirmonJob` is a [cron job](guide.html) that runs every 5 minutes (`*/5 * * * * UTC`) at priority 30.
Override either when creating it:
~~~ruby
RocketJob::Jobs::DirmonJob.create!(
cron_schedule: "*/1 * * * * UTC",
priority: 25
)
~~~
The schedule and priority can be changed at any time afterwards, either from Mission Control or in
code:
~~~ruby
RocketJob::Jobs::DirmonJob.first.update_attributes(
cron_schedule: "*/5 * * * * UTC",
priority: 20
)
~~~
Starting a second `DirmonJob` while one is already queued or running is rejected with a validation
error, so it is safe to call `create!` from deploy automation guarded by a rescue, or use the
non-raising `create`.
## High availability
`DirmonJob` has no dedicated process and no single point of failure. After each scan completes it
schedules the next instance of itself and then destroys the current one. Because Rocket Job picks any
available worker for the next run, scanning continues even as individual workers and containers come
and go. There is only ever one `DirmonJob` queued or running at a time.
If a scan raises an exception, the responsible `DirmonEntry` is moved to the `failed` state with the
exception recorded, so the rest of the entries keep working and the failure can be investigated and
re-enabled from Mission Control. A file that was removed after it was found is not a failure: it is
skipped. A missing archive location, such as an S3 bucket that does not exist, still fails the entry.
An entry whose storage cannot be reached, such as an SFTP server that is restarting
(`IOStreams::Errors::Unavailable`), is not failed straight away. A warning is logged and the entry is
scanned again on the next run, so it recovers on its own once the storage is back. Only once its
storage has been unavailable for longer than `max_unavailable_seconds`, an hour by default, is the
entry failed, since by then the cause may not be temporary, such as a server that stays down. A host
name that does not exist, such as a mistyped one, is not reported as unavailable, so it fails the entry
on the first scan. A host that only resolves over a VPN therefore fails its entry while the VPN is down.
Re-enabling the entry starts a new period.
~~~ruby
# In an initializer: allow the storage of an entry to be unavailable for up to 2 hours.
RocketJob::DirmonEntry.max_unavailable_seconds = 2 * 60 * 60
# Or fail an entry the first time its storage is unavailable, as before.
RocketJob::DirmonEntry.max_unavailable_seconds = 0
~~~
## Managing Dirmon in the web UI
Everything above can be done from [Rocket Job Mission Control](mission_control.html): create and edit
entries, set their `user_editable` job fields, enable, disable, and re-enable them, inspect failures,
and adjust the `DirmonJob` schedule and priority. Because Dirmon ships with Rocket Job, this UI is
available with no extra code, which is exactly what teams otherwise rebuild by hand for every project.
---
## Events
Near real-time control of running Rocket Job servers, and a general purpose
publish / subscribe mechanism for your own application.
## Overview
A Rocket Job event is a small message that is published to MongoDB and then
delivered almost immediately (usually under 100 ms) to every process that has
subscribed to it. There is no separate message broker to install or operate:
events are stored in a [tailable capped collection](architecture.html) that
every Rocket Job server tails in the background.
Events are how the supervisor controls its servers. When a server is paused,
stopped, or killed from [Mission Control](mission_control.html) or from a Rails
console, an event is published and the running servers react to it right away.
Because delivery is near instantaneous across every server in the cluster,
managing a fleet of servers feels immediate instead of waiting for the next
poll interval.
Events are not limited to managing Rocket Job. Any process running in the same
application can publish events, and your own code can subscribe to both the
built-in events and to events that you define yourself.
An event has three parts:
* a **name** that identifies the subscriber it is destined for,
* an **action**, which is the method invoked on the subscriber, and
* an optional hash of **parameters** passed to that method as keyword arguments.
Publishing an event is as simple as calling `publish` on a subscriber class:
~~~ruby
RocketJob::Subscribers::Server.publish(:pause)
~~~
This can be run from a Rails console, a Rails web application, or anywhere else
in the same application that is connected to the same MongoDB.
## Built-in Subscribers
Rocket Job ships with the following subscribers. Every running server
automatically subscribes to all of them on startup, so the events below are
ready to use without any additional configuration on the servers.
### Controlling the Log Level
The most useful built-in event is changing the log level of a running
application at runtime, without restarting any process or deploying any code.
This is invaluable for diagnosing a problem in production: turn on `:debug` or
`:trace` logging, capture what you need, then turn it back down again.
Rocket Job uses [Semantic Logger](https://logger.reidmorrison.com), so the log
level can be changed globally, for a single class, or targeted at a single host
or process.
Change the global log level to `:debug` on every server:
~~~ruby
RocketJob::Subscribers::Logger.publish(:set, level: :debug)
~~~
Change it back to `:info` everywhere:
~~~ruby
RocketJob::Subscribers::Logger.publish(:set, level: :info)
~~~
Change the log level for a single class across all servers. This is the most
precise way to increase logging: turn up just the class you are investigating
and leave everything else quiet.
~~~ruby
RocketJob::Subscribers::Logger.publish(:set, level: :trace, class_name: "RocketJob::Supervisor")
~~~
The targeting arguments narrow which processes respond. Change the log level on
just one host:
~~~ruby
RocketJob::Subscribers::Logger.publish(:set, level: :debug, host_name: "server1.company.com")
~~~
Or on one specific process, by host name and process id:
~~~ruby
RocketJob::Subscribers::Logger.publish(:set, level: :debug, host_name: "server1.company.com", pid: 34567)
~~~
`class_name` and the `host_name` / `pid` targeting can be combined, for example
to raise the log level for a single class on a single process.
When workers appear to be stuck or hanging, ask them to write the backtrace of
every thread to their log file. This is one of the quickest ways to see what a
process is actually doing.
Dump every thread's backtrace on all servers:
~~~ruby
RocketJob::Subscribers::Logger.publish(:thread_dump)
~~~
Or on just one host:
~~~ruby
RocketJob::Subscribers::Logger.publish(:thread_dump, host_name: "server1.company.com")
~~~
### Managing Servers
`RocketJob::Subscribers::Server` controls running servers. By default an event
applies to every server; supply `server_id` or `name` to target one.
Stop all running servers gracefully, letting active jobs and slices finish:
~~~ruby
RocketJob::Subscribers::Server.publish(:stop)
~~~
Pause all running servers. Paused servers stop picking up new work but stay
alive:
~~~ruby
RocketJob::Subscribers::Server.publish(:pause)
~~~
Resume all paused servers:
~~~ruby
RocketJob::Subscribers::Server.publish(:resume)
~~~
Hard kill all servers immediately, without waiting for active jobs or slices to
complete:
~~~ruby
RocketJob::Subscribers::Server.publish(:kill)
~~~
Tell every server to refresh, re-evaluating its state immediately rather than
waiting for the next poll:
~~~ruby
RocketJob::Subscribers::Server.publish(:refresh)
~~~
Write the backtrace of every worker thread on every server to its log file,
useful for researching jobs or slices that appear to be stuck:
~~~ruby
RocketJob::Subscribers::Server.publish(:thread_dump)
~~~
**Targeting a single server.** Instead of acting on every server, supply the
server's `id` or `name`. Look up the server by its host name, then publish the
event with its id:
~~~ruby
server = RocketJob::Server.where(name: "myhost").first
RocketJob::Subscribers::Server.publish(:stop, server_id: server.id)
~~~
The `server_id` (or `name`) argument can be applied to any of the server events
above.
### Managing Individual Workers
`RocketJob::Subscribers::Worker` controls a single worker thread on a single
server. These events require both `server_id` and `worker_id`.
Stop worker `1` on the server named `myhost`:
~~~ruby
server = RocketJob::Server.where(name: "myhost").first
RocketJob::Subscribers::Worker.publish(:stop, worker_id: 1, server_id: server.id)
~~~
Kill a worker that is hanging:
~~~ruby
RocketJob::Subscribers::Worker.publish(:kill, worker_id: 1, server_id: server.id)
~~~
Write a single worker's thread backtrace to its log file:
~~~ruby
RocketJob::Subscribers::Worker.publish(:thread_dump, worker_id: 1, server_id: server.id)
~~~
### Refreshing Secret Config
When running Rocket Job in a container it is recommended to manage settings and
application credentials with [Secret Config](https://config.reidmorrison.com).
Rocket Job ships with a subscriber that refreshes every server's in-memory copy
of the Secret Config registry, so updated settings take effect without a
restart:
~~~ruby
RocketJob::Subscribers::SecretConfig.publish(:refresh)
~~~
Secret Config can also configure Rocket Job itself. For example, add the
following to `config/application.rb`:
~~~ruby
# Limit this server to only those job classes that match this regular expression (case-insensitive).
# Example: "DirmonJob|WeeklyReportJob"
if config.secret_config.key?("rocket_job/include_filter")
config.rocket_job.include_filter = Regexp.new(config.secret_config.fetch("rocket_job/include_filter"), true)
end
# Prevent this server from working on any job classes that match this regular expression (case-insensitive).
# Example: "DirmonJob|WeeklyReportJob"
if config.secret_config.key?("rocket_job/exclude_filter")
config.rocket_job.exclude_filter = Regexp.new(config.secret_config.fetch("rocket_job/exclude_filter"), true)
end
# Limit this server instance to the supplied mongo query filter. Supply as a string in JSON format.
# Example: '{\"priority\":{\"$lte\":25}}'"
config.rocket_job.where_filter = config.secret_config.fetch("rocket_job/where_filter", type: :json, default: nil)
config.rocket_job.max_workers = config.secret_config.fetch("rocket_job/max_workers", type: :integer, default: 10)
config.rocket_job.heartbeat_seconds = config.secret_config.fetch("rocket_job/heartbeat_seconds", type: :float, default: 15.0)
config.rocket_job.max_poll_seconds = config.secret_config.fetch("rocket_job/max_poll_seconds", type: :float, default: 5.0)
config.rocket_job.re_check_seconds = config.secret_config.fetch("rocket_job/re_check_seconds", type: :float, default: 60.0)
~~~
## Subscribing from Other Processes
Rocket Job servers subscribe to the built-in events automatically. Any other
process that should respond to events, such as a Rails web application or a
Rails console, needs to subscribe to the events it cares about and start a
listener thread.
Add the following to `config/initializers/rocket_job.rb`:
~~~ruby
unless RocketJob.server?
# Subscribe to logging events so that log levels can be changed in this process
RocketJob::Subscribers::Logger.subscribe
# Subscribe to Secret Config events
RocketJob::Subscribers::SecretConfig.subscribe if defined?(SecretConfig)
# Start the Rocket Job event listener thread
Thread.new { RocketJob::Event.listener }
end
~~~
The `unless RocketJob.server?` guard ensures this only runs in non-server
processes, since servers already subscribe and run the listener themselves.
A process only reacts to the events it has subscribed to. The example above
subscribes a web application to the Logger and Secret Config events, so a log
level change published from anywhere in the application takes effect in the web
process too.
## Custom Events
Events are a general purpose publish / subscribe mechanism. Your own
application can define subscribers to perform custom actions across every
process: clearing a connection pool, flushing a cache, reloading a feature
flag, or anything else that should happen everywhere at once.
A subscriber is any class that includes `RocketJob::Subscriber`. Each public
method is an action that can be published. Method arguments become the event's
parameters, and are passed as keyword arguments:
~~~ruby
class ExampleSubscriber
include RocketJob::Subscriber
def example
logger.measure_info "Running example event" do
puts "Put some custom code here, for example to clear out connection pools, etc..."
end
end
def example2(name:, port:)
logger.measure_info "Running example2 event" do
puts "Example2 name: #{name}, port: #{port}"
end
end
end
~~~
Register the subscriber in an initializer, for example
`config/initializers/rocket_job.rb`, so the processes that should respond to it
subscribe on startup:
~~~ruby
ExampleSubscriber.subscribe
~~~
From a Rails console or web application, invoke the action on every subscribed
process:
~~~ruby
ExampleSubscriber.publish(:example)
~~~
Pass parameters as keyword arguments. They are delivered to the action method:
~~~ruby
ExampleSubscriber.publish(:example2, name: "Jack", port: 123)
~~~
Subscribers can also take constructor arguments. Anything passed to `subscribe`
is forwarded to the subscriber's `new`, which is how the built-in `Server` and
`Worker` subscribers receive their supervisor.
## How It Works
Events are published by saving a small document into the `rocket_job.events`
capped collection in MongoDB. Every subscribed process tails that collection
with a long-polling tailable cursor, so a newly published event is picked up
within milliseconds and the matching action is invoked on each subscriber.
Because the mechanism relies on a tailable capped collection, it requires a real
MongoDB server. AWS DocumentDB does not support capped collections and therefore
cannot host Rocket Job. See [Installation](installation.html) and
[Architecture](architecture.html) for details.
A subscriber receives only the events whose name matches its own. An action that
is published but is not defined on any subscribed subscriber is simply logged
and ignored, so it is safe to publish an event before every process has been
upgraded to handle it.
---
## Mission Control: The Web UI
Rocket Job Mission Control is the web interface for managing and monitoring
[Rocket Job](index.html). It is where operators watch what the cluster is doing, retry or
abort work, drain servers for a deploy, inspect and repair failed batch jobs, and manage
[directory monitoring](dirmon.html) entries, all without writing or deploying any code.
It ships as a separate gem,
[`rocketjob_mission_control`](https://github.com/reidmorrison/rocketjob_mission_control),
so the web UI and its Rails dependencies are not loaded everywhere Rocket Job jobs are
defined or run. Workers stay lean, and the console runs wherever it is convenient to host a
small Rails app.
### A quick orientation
If you are new to Rocket Job, a handful of terms show up throughout this interface:
* A **Job** is a unit of work. It moves through a lifecycle of states (queued, running,
completed, failed, and so on) that Mission Control groups into tabs. See the
[Programmers Guide](guide.html).
* A **Batch Job** splits a large amount of data into many small **slices** that are
processed in parallel and independently. A single bad record fails only its slice, not the
whole job, which is what makes the recovery tools below possible. See
[Batch Processing](batch.html).
* A **Server** is one running Rocket Job process. Each server runs one or more **Workers**,
the threads that actually pull jobs off the queue and process them. See
[Architecture](architecture.html).
* A **Dirmon Entry** is a rule that watches a directory and starts a job whenever a matching
file arrives. See the [Dirmon guide](dirmon.html).
The top navigation bar mirrors these concepts with four sections: **Jobs**, **Servers**,
**Workers**, and **Directory Monitoring**. The rest of this page walks through each one.
### Installation
Mission Control is a Rails engine. Mount it into a new or existing Rails application.
Add it to the `Gemfile`:
~~~ruby
gem "rocketjob_mission_control", "~> 6.0"
~~~
Install it:
~~~bash
bundle install
~~~
Mount the engine in `config/routes.rb`, pointing it at whatever path you want it served
from:
~~~ruby
Rails.application.routes.draw do
mount RocketJobMissionControl::Engine => "rocketjob"
end
~~~
The application that hosts Mission Control needs the same Mongoid configuration as the
rest of the cluster (the `rocketjob` and `rocketjob_slices` clients) so that it reads and
writes the same jobs and slices. See [Installation](installation.html) for the Mongoid
setup.
Because it only needs `railties` and not a full Rails stack, Mission Control can be mounted
into a minimal app dedicated to operations. It exposes destructive actions (aborting jobs,
stopping servers, editing slice data), so put it behind your own authentication and
authorization before exposing it outside a trusted network. The next section covers the
built-in authorization.
### Access control
Mission Control authenticates nothing itself; the host app is responsible for identifying
the user. What Mission Control does provide is fine-grained **authorization**: deciding which
of its actions a given user is allowed to perform.
Authorization is built on the
[access-granted](https://github.com/chaps-io/access-granted) gem, a lightweight,
policy-based, role-driven authorization library. A few of its concepts are worth knowing
before tuning the rules:
* **Policy.** A single policy object holds all the rules. Mission Control ships one,
`RocketJobMissionControl::AccessPolicy`, whose `configure` method defines every role.
* **Roles.** Permissions are grouped into named roles rather than scattered through
conditionals. A user is granted one or more roles and inherits the permissions those roles
allow.
* **Whitelist model.** Rules say what a role *can* do; anything not explicitly granted is
denied. There are no sprawling "allow this, but not that" exceptions to reason about.
* **Priority ordering.** Roles are evaluated top to bottom. The most privileged role sits at
the top, and the first role that grants a permission wins, so checks stay fast and
predictable.
* **Conditional permissions.** A permission can carry a block that further scopes it, for
example restricting a user to acting only on their own jobs.
#### The default roles
Mission Control defines seven roles over the `RocketJob::Job`, `RocketJob::DirmonEntry`,
`RocketJob::Server`, and `RocketJob::Worker` documents:
| Role | Grants |
| --- | --- |
| `admin` | Create and destroy jobs; destroy Dirmon entries. |
| `editor` | View, edit, and update the data inside a batch job's slices, including encrypted records. |
| `operator` | Stop, kill, pause, resume, and destroy servers; destroy zombies; request thread dumps. |
| `manager` | Edit, pause, resume, retry, abort, fail, update, and run jobs now. |
| `dirmon` | Create, edit, update, copy, replicate, enable, and disable Dirmon entries. |
| `user` | Edit, pause, resume, retry, abort, and update jobs, but only the user's own jobs (where the job's `login` matches). |
| `view` | Read-only access to jobs, Dirmon entries, servers, and workers. |
Roles are **hierarchical**. They are ordered from most to least privileged (`admin`,
`editor`, `operator`, `manager`, `dirmon`, `user`, `view`), and granting a role also grants
every role below it. So an `admin` can do everything, a `manager` also gets `dirmon`, `user`,
and `view` permissions, and a `view` user gets read-only access and nothing more.
The `user` role is special: its permissions are scoped by a `login`, so a user granted that
role can only act on jobs whose `login` matches their own. Supply the current user's login
from the configuration callback described below.
**When no authorization is configured, every request is treated as a full `admin`.** This
keeps development friction-free, and makes wiring up your own authorization an opt-in step.
Configure it before exposing Mission Control beyond a trusted network.
### Configuration
Authorization is wired up with a single callback in an initializer in the host application,
for example `config/initializers/rocket_job_mission_control.rb`:
~~~ruby
RocketJobMissionControl::Engine.config.rocket_job_mission_control.authorization_callback =
lambda do
{
roles: current_user.rocket_job_roles, # e.g. [:manager, :dirmon]
login: current_user.email
}
end
~~~
The callback:
* Returns a hash with `roles` (an array of role names from the table above) and, optionally,
a `login` used to scope the `user` role.
* Is evaluated in the controller instance (`instance_exec`), so it can read `session`,
`request`, and any `current_user`-style helper your authentication layer provides. This is
how per-request, per-user roles are computed.
* Returning an empty `roles` array grants no permissions (read nothing, do nothing), which is
the safe default for an unauthenticated request.
Supplying an unknown role name raises an `ArgumentError`, so typos surface immediately rather
than silently granting or denying access.
To change the permissions themselves rather than who receives which role, supply your own
policy class. Define a class that includes `AccessGranted::Policy` (subclassing the shipped
`RocketJobMissionControl::AccessPolicy` is the easiest starting point) and point the engine
at it:
~~~ruby
class MyAccessPolicy < RocketJobMissionControl::AccessPolicy
def configure
super # keep the built-in roles, then add or override below
role :auditor do
can :read, RocketJob::Job
end
end
end
RocketJobMissionControl::Engine.config.rocket_job_mission_control.access_policy_class =
MyAccessPolicy
~~~
`access_policy_class` accepts either the class itself or a String naming it (for example
`"MyAccessPolicy"`), which avoids autoloading the class too early from an initializer. When
it is not set, Mission Control uses `RocketJobMissionControl::AccessPolicy`. Because
access-granted is a plain authorization library, the same `role`/`can` API shown in the
shipped policy is all a custom policy needs.
### Monitoring jobs
The interface opens on the list of running jobs, newest first. Each entry shows:
* The class name of the job.
* An icon indicating the job's state.
* A duration that means different things depending on state:
* **Completed:** how long the job took to run.
* **Queued:** how long it has been waiting.
* **Running:** how long it has been processing.
* **Failed or aborted:** how long it ran before it stopped.
* For running jobs, a progress bar showing percent complete.
Jobs are grouped by state, each on its own tab in the left sidebar:
* **Running** is the default view.
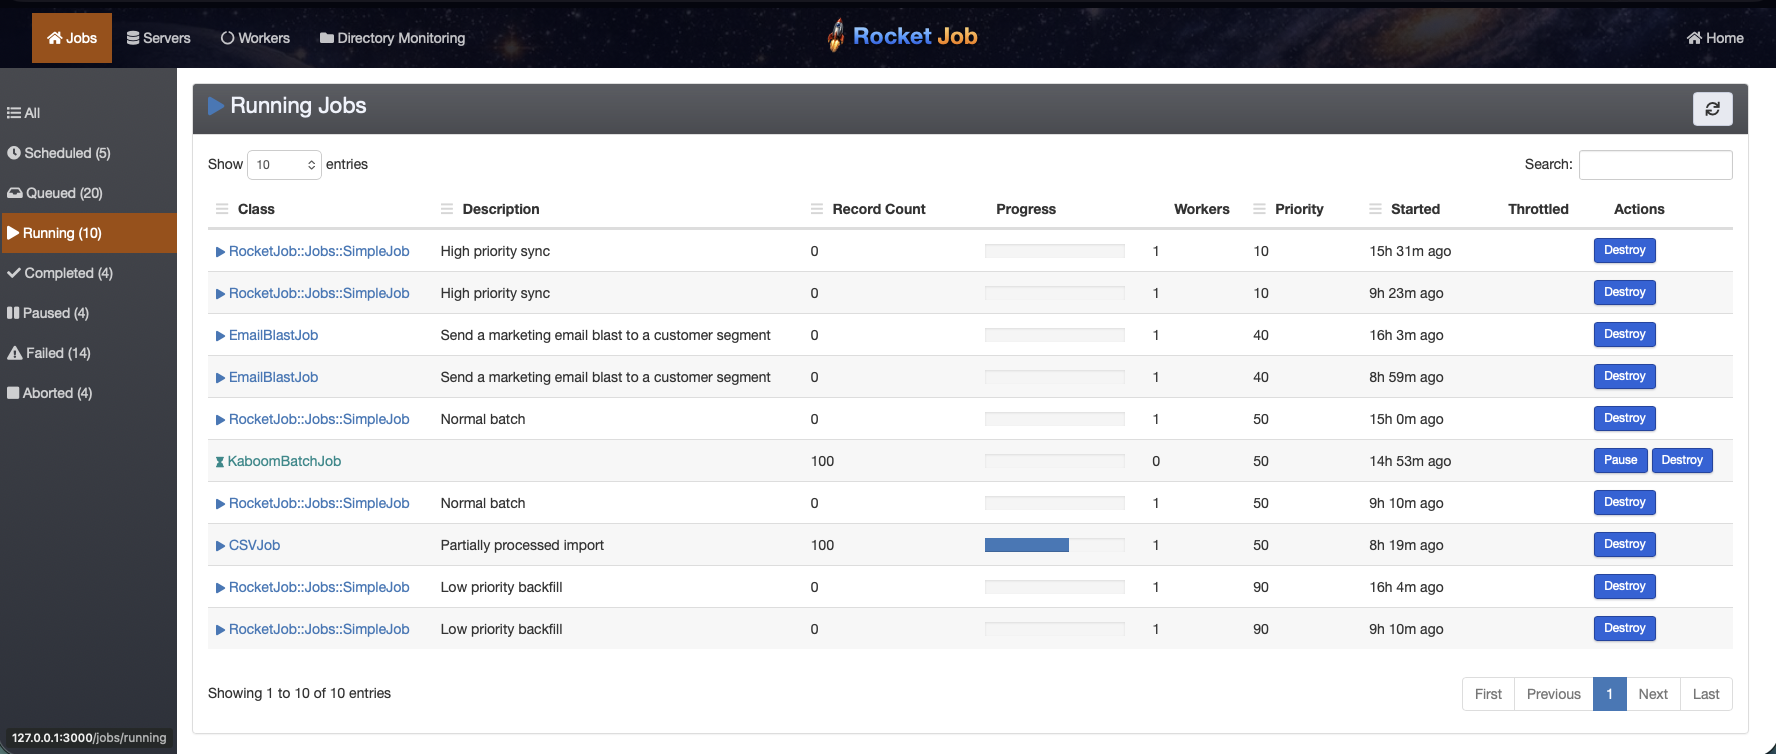
* **Scheduled** lists jobs set to run in the future, including recurring
[Cron jobs](guide.html). Select **Run** on any scheduled job to run it immediately
instead of waiting for its next scheduled time.
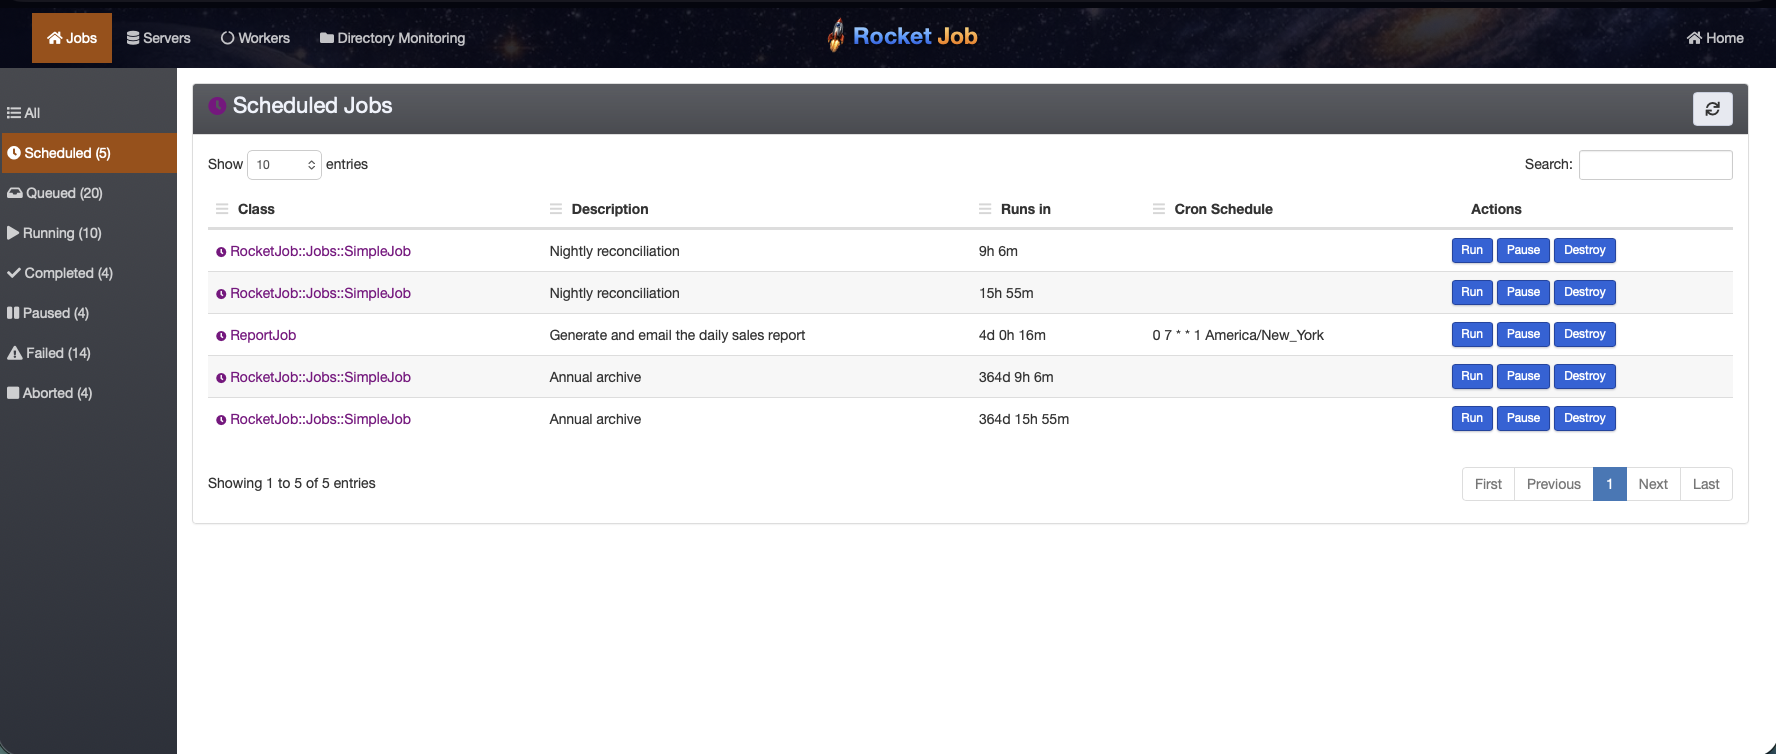
* **Queued** lists jobs waiting for a free worker.
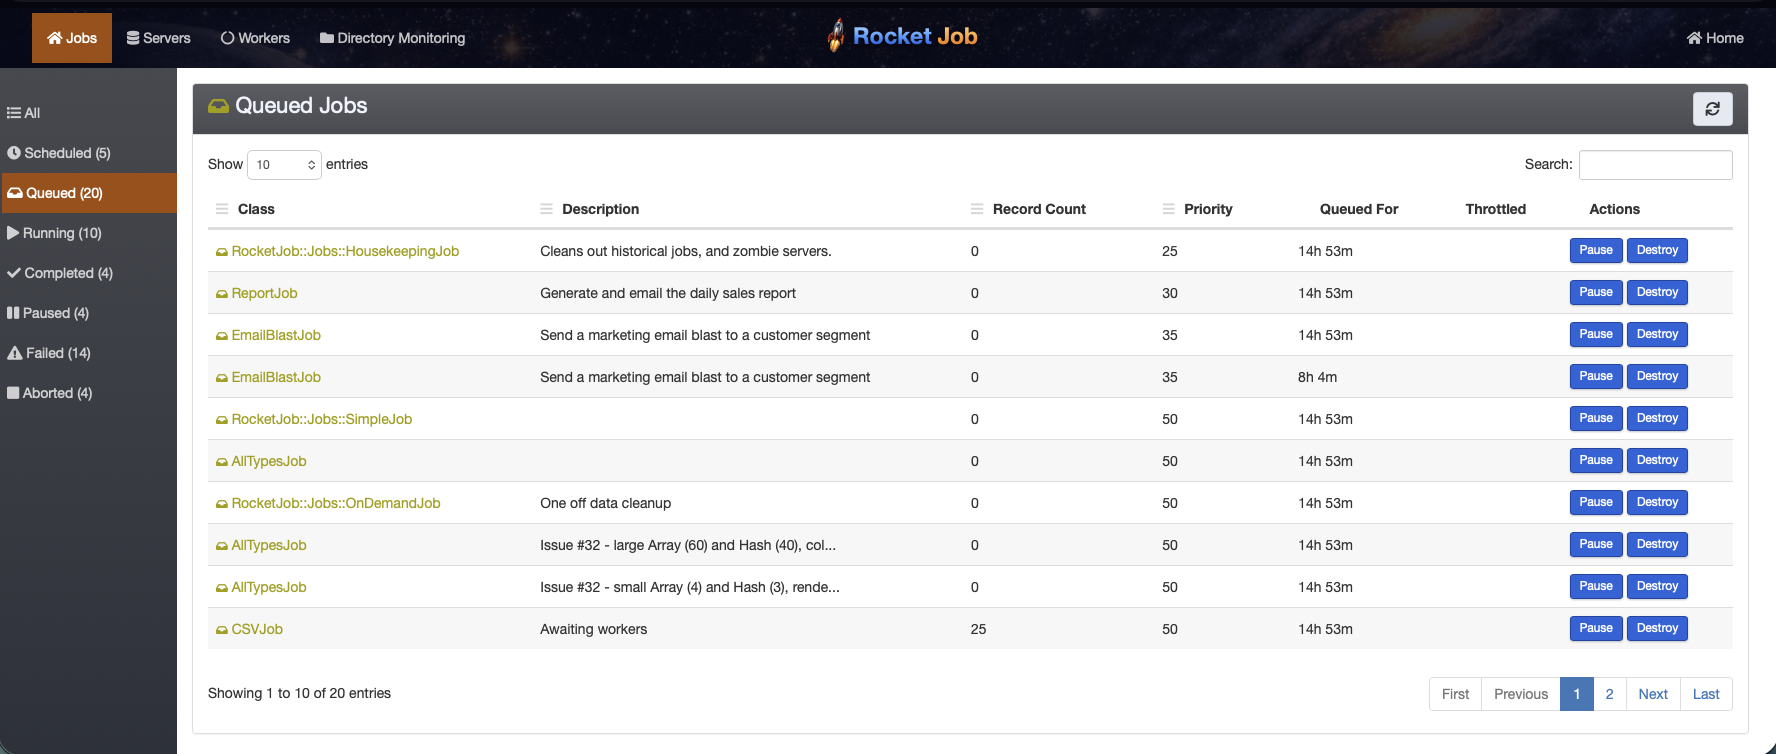
* **Completed** lists finished jobs. Only jobs with `destroy_on_complete == false` are kept
and shown here; by default completed jobs delete themselves.
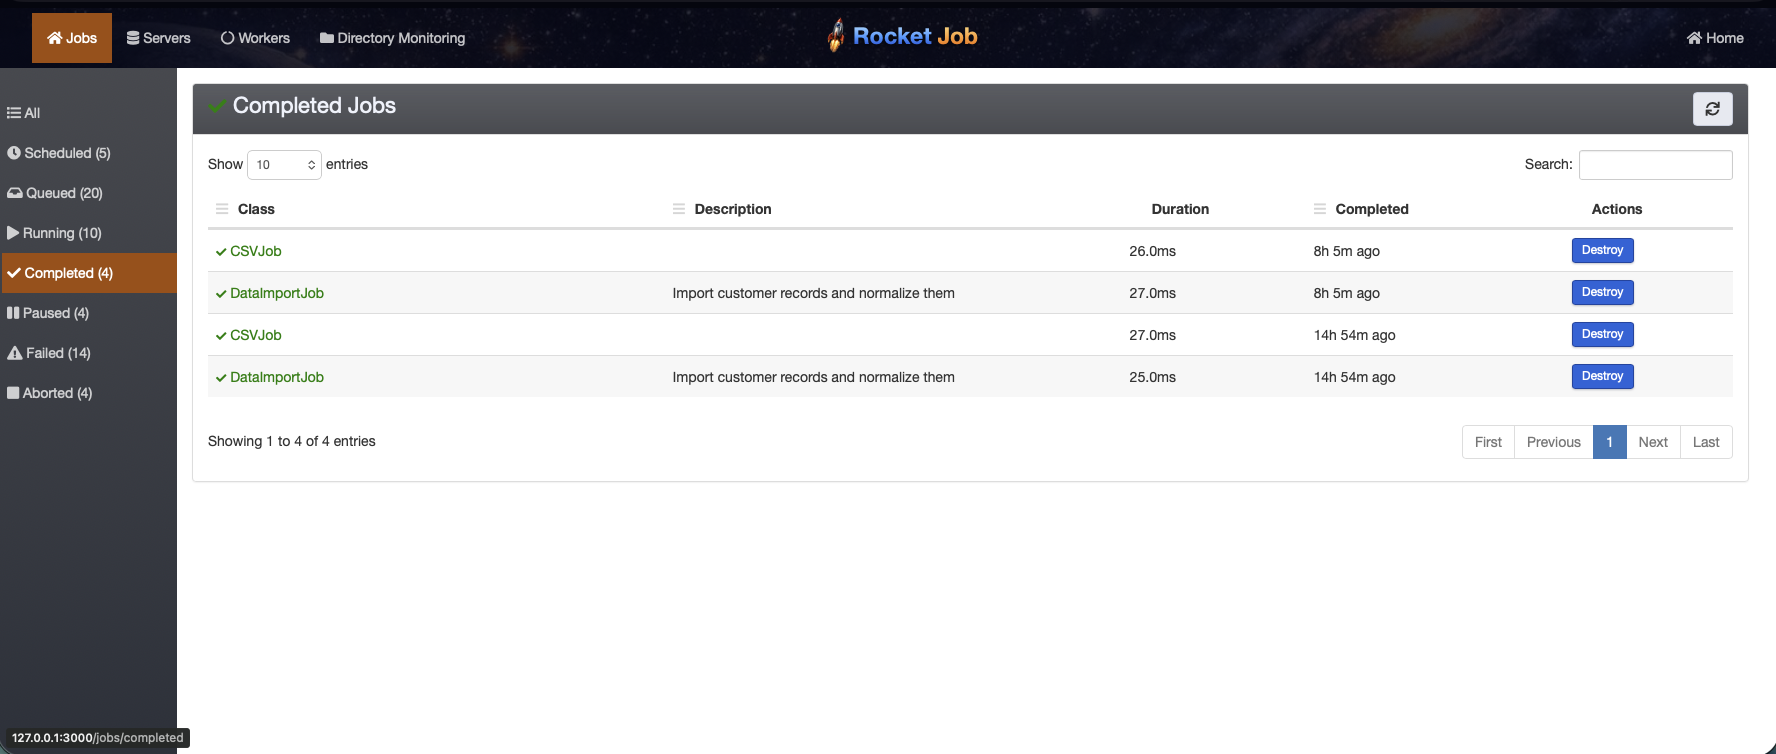
* **Paused** lists jobs whose processing has been temporarily stopped.
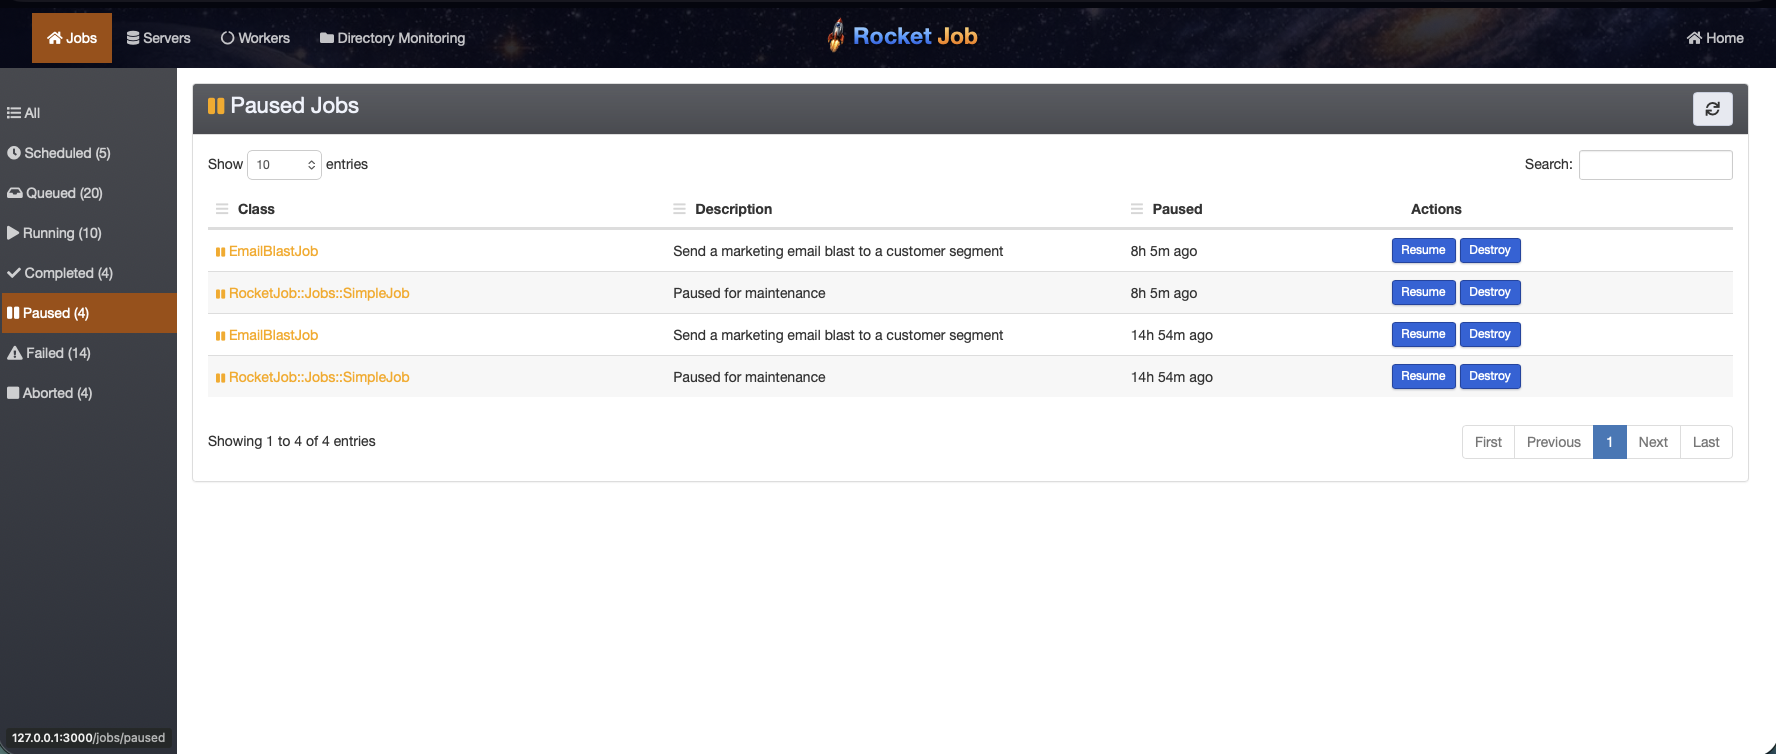
* **Failed** lists jobs that raised an exception. The failure, including the backtrace, is
recorded on the job so it can be inspected and retried.
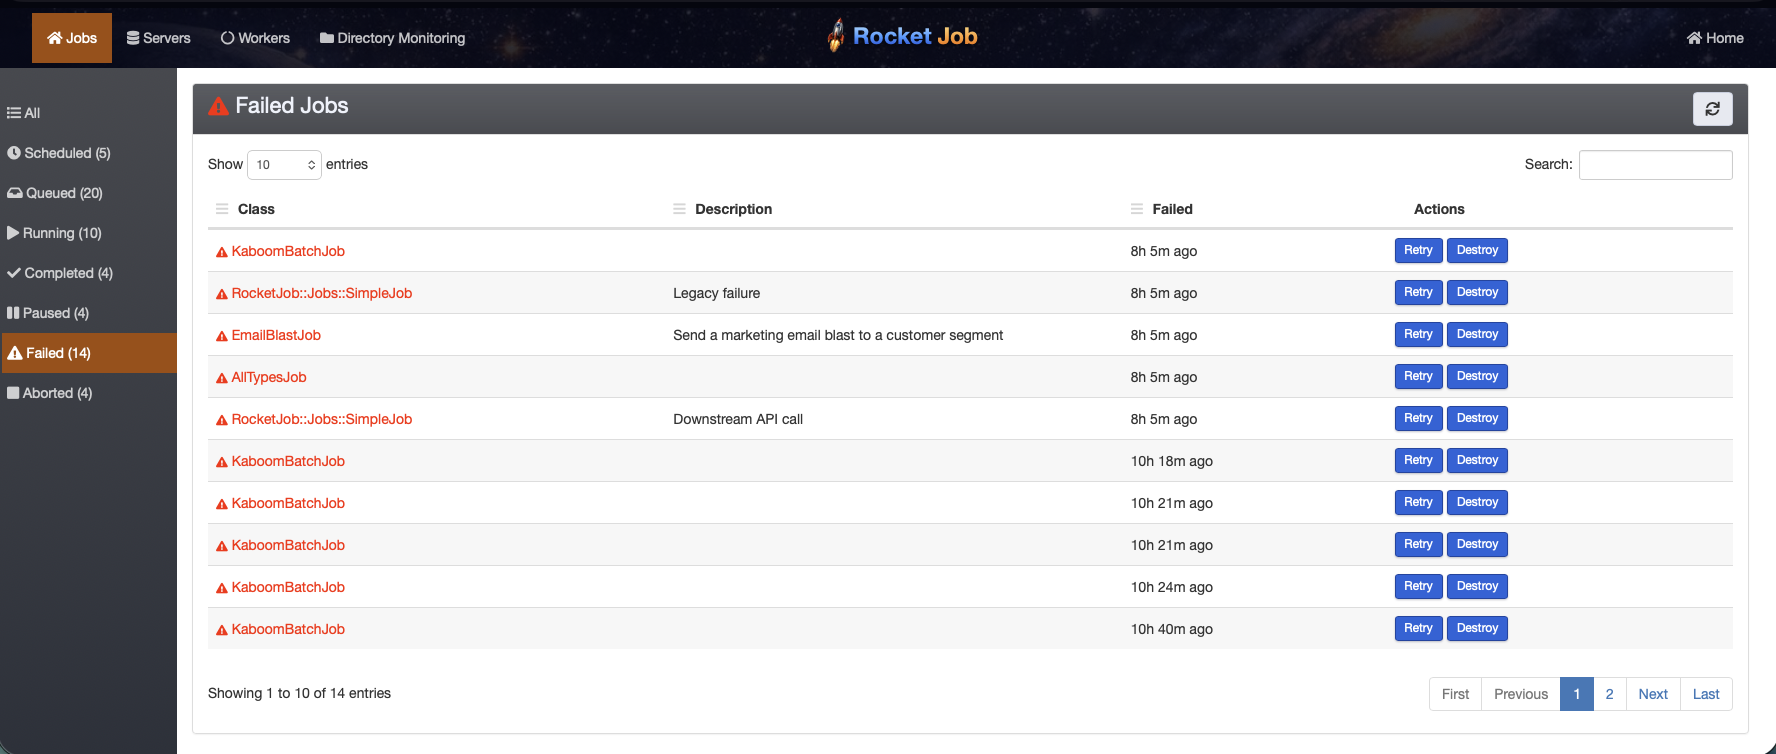
* **Aborted** lists jobs that were stopped and cannot be retried.
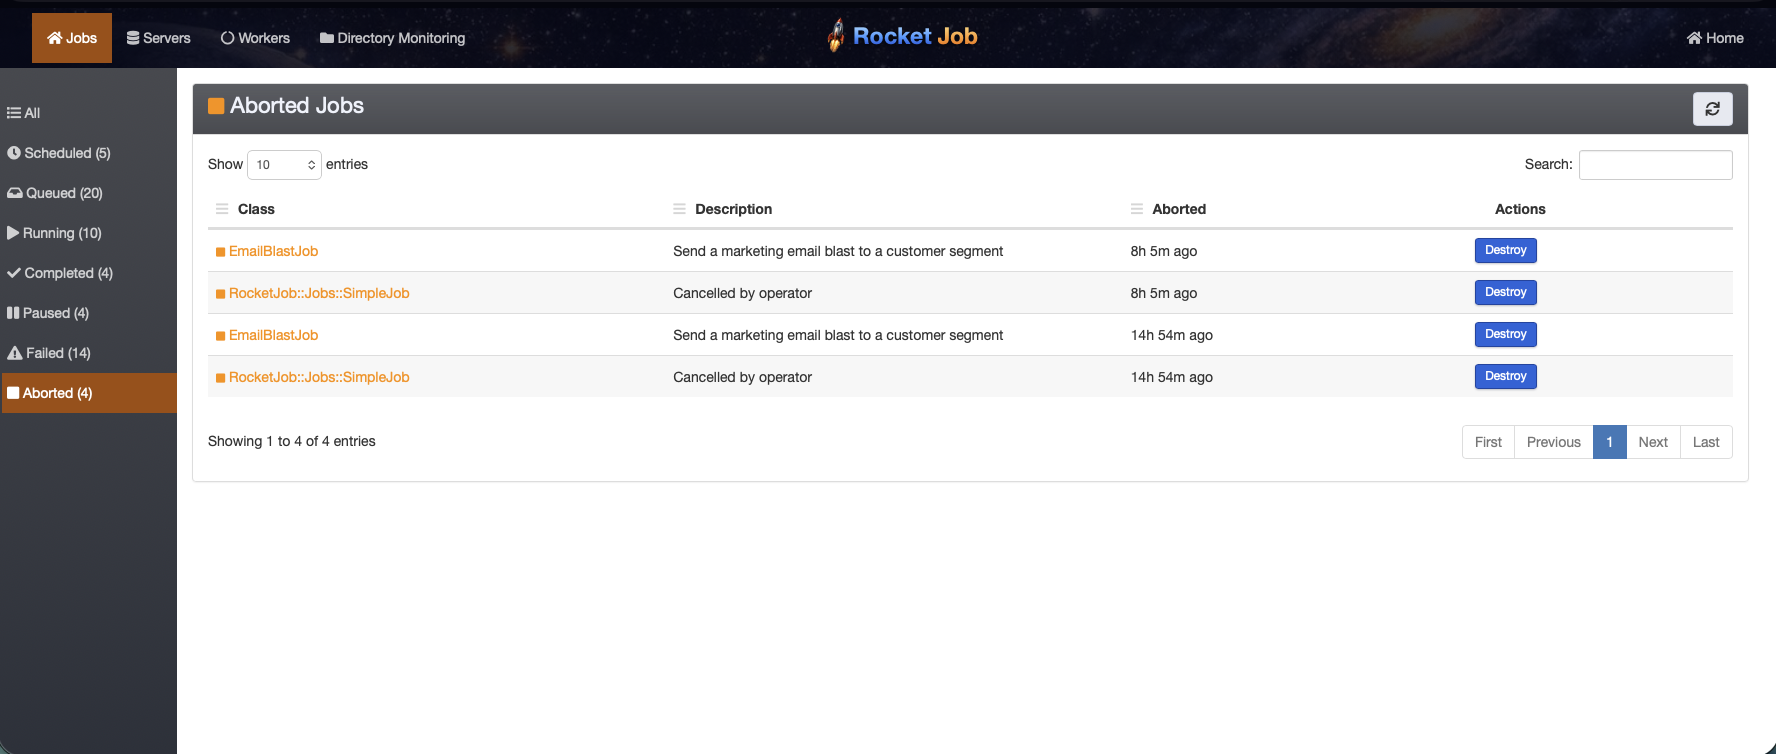
The **All** tab lists every job regardless of state, with a search box for finding a
specific job by class or description. The valid actions for each job (Retry, Pause, Destroy,
and so on) are available inline, so common operations can be done without opening the job.
### Managing a job
Select any job to open its detail page. It shows the job's current state, its fields and
timing, and the actions that are valid for its current state. For a
[batch job](batch.html), the **Details** panel also shows the record count, progress,
estimated time remaining, and a **Slices** bar that breaks the work down into queued,
active, failed, and completed slices at a glance.
The available actions are:
* **Retry** restarts a failed job from where it left off. For [batch jobs](batch.html) only
the unprocessed and failed slices are run again, so retrying a large job does not reprocess
records that already succeeded.
* **Pause** temporarily stops a running or queued job; it resumes only when **Resume** is
selected. Batch jobs can be paused mid-flight because they are pre-empted between slices.
A simple (non-batch) job is only checked between runs, so pausing one does not interrupt a
`#perform` that is already in progress.
* **Resume** continues a paused job.
* **Fail** stops a running or queued job and marks it failed. A failed job can be retried
later.
* **Abort** stops a running or queued job permanently; an aborted job cannot be retried.
Aborting or failing a batch job cleans up its input and output slice collections.
* **Destroy** removes the job from the system entirely.
A failed job shows the captured exception so the cause can be diagnosed before retrying. The
**Slices** bar turns solid red when every slice has failed, which is a quick signal that the
failure is systemic rather than caused by a few bad records.
### Recovering a failed batch job
When a [batch job](batch.html) fails, the problem is often a handful of bad records rather
than the whole data set. Because each slice fails independently, Mission Control lets you
find the offending records, fix or remove them, and retry, all without rerunning the records
that already succeeded.
The failed job's detail page includes an **Exceptions** section that groups the failures by
exception class and lists the messages raised. This is the fastest way to tell whether every
slice failed for the same reason or for several different ones.
Select an exception class to open its detail page. It shows the class name, message, and the
record number that triggered the failure, along with the backtrace (with a **Full Backtrace**
toggle for the complete stack). The arrows at the top step through the other failed
exceptions on the job.
Select **View Slice** to see the actual records in the failed slice. The record that raised
the exception is highlighted, and every record has an **Edit** button.
Editing a record opens it in a text area. Correct the data and select **Save** to put the
repaired record back into the slice, or select **Delete** to drop a record that should not
be processed at all. Unprintable bytes are shown as `\xHH` escapes (for example a null byte
as `\x00`) and are converted back to the original bytes when saved, so binary and oddly
encoded data can be edited safely.
Once the bad records are fixed or removed, **Retry** the job. Only the previously failed and
unprocessed slices run again, so the job finishes without redoing the records that already
succeeded.
### Monitoring workers
The **Workers** view lists every active worker across the cluster and the job each one is
currently processing. Each row shows the worker name (in `hostname:pid:worker-NNN` form), the
job class it is running (linked to that job), the job's description, and how long the worker
has been on its current work. It is the quickest way to see whether the cluster is busy and
where its capacity is going right now.
Because a single server runs many workers, the same server name appears on several rows when
it is processing several jobs at once. Use the refresh control at the top right to re-read the
current state.
### Managing servers
The **Servers** view lists the running Rocket Job server processes (each `Server` is one
running process; see [Architecture](architecture.html)), grouped in the sidebar by state:
starting, running, paused, stopping, and zombie. Each row shows the hostname and PID, the
current and maximum worker counts, when the server started, and when it last checked in.
Servers can be controlled from here without shell access to the hosts:
* **Pause** / **Resume** an individual server to stop or restart it pulling new work.
* **Stop** an individual server to shut it down gracefully.
* **Pause All**, **Resume All**, and **Stop All** apply the same actions to every server at
once, which is useful for draining the cluster before a deploy and bringing it back
afterward.
These actions are delivered to the servers over Rocket Job's MongoDB-backed
[pub/sub mechanism](events.html), so they take effect across every process in the cluster
without a separate message broker.
#### Zombie servers
Every server writes a periodic heartbeat. A server that stops checking in, usually because
its process was terminated abnormally rather than shut down gracefully, is flagged as a
**zombie** so dead processes can be spotted and cleaned up.
Zombies matter because a job that was being processed by a server that died would otherwise
sit stalled. Rocket Job's `HousekeepingJob` watches for zombie servers and re-queues any jobs
they were processing so another worker can pick them up. You can also clear them by hand:
**Destroy zombies** removes all of them at once, or use the per-row action to destroy a
single one.
### Managing directory monitors
Mission Control includes a full management screen for [Dirmon](dirmon.html), Rocket Job's
directory monitor. A Dirmon entry watches a path pattern and starts a job whenever a matching
file appears, so the files and schedules a system reacts to can be changed from the web UI
without a code deploy.
The **Directory Monitoring** view lists every entry with its name, job class, and the file
pattern it watches. Entries are grouped in the sidebar by state (pending, enabled, failed,
disabled), and each entry's name is colored and icon-tagged by its state.
Select **Create** to add a new entry. At minimum an entry needs a name, the job class to
start, and a pattern (a glob such as `input_files/orders/*.{csv,txt}`) identifying the files
to watch. An optional archive directory tells Rocket Job where to move each file after it has
been queued. The **properties** button reveals the job's own fields so their default values
can be set on the entry.
Selecting an entry opens its detail page, showing its current state, job class, pattern,
archive directory, and any job properties. From here an entry can be enabled or disabled,
edited, copied to a new entry, or destroyed.
Editing works the same way as creating, on the same form. A **failed** entry, one whose last
run raised an error, can be corrected here and re-enabled in place.
See the [Dirmon guide](dirmon.html) for what each field controls and how patterns and
archiving behave.
---
## Deployment
A Rocket Job "server" is the `bin/rocketjob` process. It registers itself in MongoDB, starts a
pool of worker threads (10 by default), and pulls queued jobs to run. Deploying Rocket Job means
running one or more of these processes and pointing them at your MongoDB.
You scale by running more servers. There is no central coordinator to install: every server claims
work directly from MongoDB using atomic operations, so you can start and stop servers freely. To
deploy new code, build a new image (or pull new code) and restart the servers.
This guide covers the two common ways to run servers, how to make MongoDB highly available, and the
one-time steps to perform after the first deployment. It assumes you have already configured
`config/mongoid.yml` as described in the [Installation Guide](installation.html#configure-mongodb).
## Deploy with Docker
Running each server in a self-contained Docker container is the simplest option in most cloud
environments. Configure your platform (ECS, Kubernetes, Nomad, and so on) to run the desired number
of containers and to restart them automatically when they exit. New code is then rolled out by
restarting the containers, and the cluster can be grown or shrunk based on load.
### Step 1: Create a Dockerfile
Add a file named `Dockerfile` to the root of your application:
~~~dockerfile
FROM ruby:3.4
WORKDIR /opt/rocketjob
# Optional: database client libraries. Only needed when jobs read directly
# from MySQL or PostgreSQL (for example a Batch job using upload_arel).
# Remove this block if your jobs do not touch a relational database.
RUN set -ex \
&& apt-get update \
&& apt-get install -y --no-install-recommends default-mysql-client postgresql-client \
&& rm -rf /var/lib/apt/lists/*
# Copy the application code into the image.
COPY . .
# Install gems, skipping the development and test groups.
RUN bundle config set --local without 'development test' \
&& bundle install --jobs 4 --retry 5 --quiet
# Start a Rocket Job server. Logs go to stdout so the container platform can collect them.
CMD ["bin/rocketjob"]
~~~
Use a Ruby version that Rocket Job supports (3.2, 3.4, or 4.0). See
[Compatibility](installation.html#compatibility).
Add `--quiet` to the `CMD` if you would rather log only to a file instead of stdout, for example
`CMD ["bin/rocketjob", "--quiet"]`.
### Step 2: Build the image
~~~bash
docker build -t rocketjob_server .
~~~
### Step 3: Tell the server where MongoDB is
The server reads `config/mongoid.yml`. The challenge in production is supplying credentials and host
names without baking them into the image.
**Local testing.** To run the image against a MongoDB already running on your host (per the
[Installation Guide](installation.html#install-mongodb)), set the MongoDB hostname to
`host.docker.internal:27017` so the container can reach out to the host.
**Production.** Store all configuration in a central store using
[Secret Config](https://config.reidmorrison.com), and override individual settings with environment
variables where needed. Pass environment variables into the container with Docker's
`--env-file` option (see `docker run --help`), or through your orchestrator's secret mechanism.
### Step 4: Run the server
Start a server in the background and remove the container when it exits:
~~~bash
docker run -d --rm rocketjob_server
~~~
Run that command once per server you want in the cluster, or let your orchestrator manage the
replica count.
### Useful Docker commands
~~~bash
# Open a bash shell in a fresh container
docker run -it --rm rocketjob_server bash
# Open a Rails console in a fresh container
docker run -it --rm rocketjob_server bin/rails c
# List running containers, then attach a shell to one of them
docker ps
docker exec -it /bin/bash
# Stop a running container
docker kill
# Clean up dangling and untagged local images
docker system prune -f
~~~
## Deploy with Capistrano
For traditional (non-containerized) servers, the recipe below starts and stops Rocket Job processes
over SSH. Each `bin/rocketjob` process runs detached with `nohup`, writing to a log file.
~~~ruby
# ====================================
# Rocket Job Server Tasks
# ====================================
namespace :rocketjob do
desc 'Start rocket_job servers. Optional: HOSTFILTER=server1,server2 count=2 workers=10 include="DirmonJob|WeeklyReportJob"'
task :start do
count = (ENV["count"] || 1).to_i
include_filter = "--include #{ENV['include']}" if ENV["include"]
workers = "--workers #{ENV['workers']}" if ENV["workers"]
count.times do
run "cd #{component_path} && nohup bin/rocketjob --quiet #{include_filter} #{workers} >> #{component_path}/log/rocketjob.log 2>&1 & sleep 2"
end
end
desc "Stop all rocket_job servers on a host. Optional: HOSTFILTER=server1,server2"
task :stop do
run "pkill -u rails -f bin/rocketjob"
end
end
~~~
`pkill` sends `SIGTERM`, which Rocket Job handles as a graceful shutdown: each server finishes the
jobs already in progress before exiting. To stop servers without shelling into each host, use the
event-based command instead, which signals servers through MongoDB:
~~~bash
bin/rocketjob --stop
~~~
### Limiting a server to specific jobs
The `--include` flag above restricts a server to job classes matching a regular expression, so you
can dedicate a pool of servers to a heavy or latency-sensitive job class while another pool handles
everything else. The companion `--exclude` and `--where` flags are documented in the
[Programmer's Guide](guide.html#limiting-which-jobs-a-server-runs).
## High-availability MongoDB
For a small production install, a single MongoDB server alongside the Rocket Job processes is
sufficient. For high availability, run a [MongoDB replica set](https://www.mongodb.com/docs/manual/replication/).
A common setup is two full data-bearing members plus one arbiter, or three full members. Placing one
member in a second data center allows failover across data centers.
If the primary goes down, the replica set elects a new primary automatically. Rocket Job detects the
change, reconnects to the new primary, and continues processing without failed jobs.
Point `config/mongoid.yml` at the replica set by listing all members in the connection URI, for
example:
~~~yaml
uri: mongodb://user:secret@server1.example.org:27017,server2.example.org:27017/rocketjob_production?replicaSet=rs0
~~~
## Running multiple servers per host
A single host can run several Rocket Job servers, each with its own pool of worker threads (10 by
default). Adjust the thread count per server with `--workers`:
~~~bash
nohup bundle exec rocketjob --quiet --workers 10 >> log/rocketjob.log 2>&1 &
~~~
The right number of servers and threads per host is found through load testing. The goal is to
maximize throughput without saturating the host's CPU, memory, or disk, or overwhelming MongoDB.
The web interface, [Mission Control](mission_control.html), is a Rails engine. Mount it into your
Rails application and run it on multiple hosts behind a load balancer for high availability.
## After deployment
### Start the directory monitor
If you use [Dirmon](dirmon.html) to pick up files as they arrive, the directory monitor must be
created once per environment from an application console (`RocketJob::Jobs::DirmonJob.create!`). It
then reschedules itself, so this is a one-time step. See
[Starting the directory monitor](dirmon.html#starting-the-directory-monitor) for the details.
### Monitor MongoDB
Because all coordination happens in MongoDB, watching the database is the best way to observe the
cluster under load. `mongostat` reports per-second operation counts across every member:
~~~bash
mongostat --host localhost:27017 --discover
~~~
Replace `localhost:27017` with one of your MongoDB hosts. The `--discover` flag follows the rest of
the replica set automatically.
---
## Architecture and Internals
This page explains how Rocket Job works under the hood: the concurrency model, how jobs are stored
and claimed, and why the design is reliable and scalable. For the day-to-day programming interface,
see the [Programmer's Guide](guide.html) and the [Batch Guide](batch.html). A
[class diagram](#class-diagram) of the core relationships is further down this page.
## Concurrency model
A Rocket Job server process runs a pool of worker threads, one job per thread. Using threads rather
than forked processes has several benefits:
* **Lower memory use.** Compiled Ruby code and any in-memory caches are loaded once per process and
shared across all of that process's worker threads, instead of being duplicated per fork.
* **Higher throughput.** Threads are cheaper to start and coordinate than separate processes.
* **Centralized supervision.** A single management thread monitors all the worker threads in the
process and maintains the server heartbeat for the whole process.
Each worker is independent of the others, so it runs as fast as Ruby allows without coordinating
with its peers. Because many workers run `perform` at the same time, job code must be thread-safe.
The rules for writing thread-safe jobs are in
[Thread Safety](guide.html#thread-safety) in the Programmer's Guide.
## In-place processing in MongoDB
Rocket Job processes a job "in place" in [MongoDB](https://www.mongodb.com). A job is created once
and stored entirely as a single document, so everything about it lives in one place:
* its [state](guide.html#the-job-lifecycle): queued, running, failed, aborted, paused, or completed
* its percent complete
* its user-defined fields
* its last exception, timings, and worker name
Because the job only lives in one document, its status is immediately visible in
[Mission Control](mission_control.html) without updating any separate store.
The single-document approach is made efficient by MongoDB's
[`find_and_modify`](https://www.mongodb.com/docs/manual/reference/command/findAndModify/), which
atomically finds the highest-priority ready job and marks it as running in one operation. This lets
any of hundreds of workers claim work without the locking contention that a relational database
would suffer, and without a separate message broker. MongoDB is both the queue and the system of
record, and it spills from memory to disk, so a single job can hold far more input and output than
fits in RAM.
For how this extends to parallel batch processing, where the input is split into independently
claimed slices, see [How batch jobs work](batch.html#how-batch-jobs-work) and
[How it works](index.html#how-it-works).
## Reliability
If a worker process crashes while processing a job, the job is never lost. It stays in MongoDB, and
when the dead server is cleaned up its in-flight jobs are automatically re-queued and picked up by
another worker. For batch jobs the same is true at the slice level: only the slices that were in
flight are re-queued, and already-completed slices are not reprocessed.
## Scalability
Rocket Job scales linearly: adding more servers adds CPU, memory, and local disk, and doubling the
number of worker servers should roughly double throughput. In practice the bottleneck moves to the
databases, networks, or external services that jobs call into during processing.
Those downstream bottlenecks can be scaled independently. For example, read-heavy jobs can offload
their reads to database replicas. [ActiveRecord Slave](https://github.com/reidmorrison/active_record_slave)
redirects ActiveRecord reads across one or more replica servers, spreading the load generated by a
large pool of workers. Within a single job, [throttles](guide.html#throttling) and
[batch worker limits](batch.html#throttling-concurrent-workers) cap how hard a shared resource is
hit, so adding workers does not overwhelm it.
## Performance
The benchmarks below were run with the bundled `rocketjob_perf` (simple jobs) and
`rocketjob_batch_perf` (batch jobs) scripts. They are historical numbers, captured on modest
hardware, and are included to show the order of magnitude Rocket Job reaches and how it scales with
more processes. Real throughput depends on your hardware, MongoDB deployment, and what each job does.
Both tests used the same setup:
* 13" MacBook Air (M5)
* macOS 26.5.1
* Ruby 3.4.9 (CRuby)
* MongoDB 8.2.11 in a default Docker container
Start the worker processes by running the following in 3 separate windows:
~~~
bundle exec rocketjob --log_level warn --workers 5
~~~
### Simple jobs
Run a quick test with `bundle exec rocketjob_perf -c 1000`, or the full test with
`bundle exec rocketjob_perf`. With 15 workers distributed across 3 processes:
~~~
{
:count => 100000,
:duration => 70.493,
:jobs_per_second => 1418
}
~~~
1,418 jobs per second, processed reliably, in priority order, and with full visibility of every job.
### Batch jobs
Run a quick test with `bundle exec rocketjob_batch_perf -c 1000`, or the full test with
`bundle exec rocketjob_batch_perf`. With 15 workers distributed across 3 processes:
~~~
{
:count => 10000000,
:duration => 93.411,
:records_per_second => 107053.773,
:workers => 15,
:worker_processes => 3
}
~~~
Over 100,000 records per second on a single laptop. Increasing `slice_size` further raises the processing rate, and enabling
or disabling compression and/or encryption does not appear to have a significant impact on
processing times.
## Public vs internal API
The public interface is small and deliberately so. Application code subclasses `RocketJob::Job`,
optionally mixes in capability modules such as `RocketJob::Batch`, defines typed fields, and
implements `#perform`. Queuing, downloading results, and the documented
[job state transitions](guide.html#the-job-lifecycle) round out the surface that is guaranteed to
remain stable.
Everything else, the plugin modules under `RocketJob::Plugins`, the slicing machinery under
`RocketJob::Sliced`, and the runtime classes (`Supervisor`, `Server`, `WorkerPool`, `Worker`,
`Subscriber`), is internal. It is documented here for contributors extending Rocket Job, not for
callers using it, and may change between minor releases as long as the public job interface is
preserved.
## The job is a composition of plugins
`RocketJob::Job` is deliberately almost empty: it composes its behavior by including a stack of
modules, each an `ActiveSupport::Concern` that contributes fields, callbacks, validations, and
methods (`Plugins::Document`, `Plugins::Job::Model`, `Persistence`, `Callbacks`, `Logger`,
`StateMachine`, `Worker`, `Throttle`, and so on). `Plugins::Document` is the concern that pulls in
`Mongoid::Document` and pins the job to the `rocketjob` MongoDB client. The
[state transitions](guide.html#the-job-lifecycle) (queued to running to
completed / failed / aborted / paused) are driven by the `aasm` gem via the state machine plugins.
Optional capabilities are themselves modules that a job opts into: [Batch](batch.html),
[Cron](guide.html#scheduled-jobs), `Singleton`, [Retry](guide.html#automatic-retry),
`ProcessingWindow`, `Transaction`, and `ThrottleDependentJobs`.
This composition is what makes Rocket Job extensible: your own behavior can be packaged as a plugin
and included into any job, exactly like the built-in ones. See
[Extending Jobs with Plugins](guide.html#extending-jobs-with-plugins) in the Programmer's Guide for
how to write one.
## Batch jobs and slices
`RocketJob::Batch` is a concern that layers slicing on top of a job. Input and output are organized
into **categories** (`Category::Input` / `Category::Output`), each with its own serializer (plain,
compressed, encrypted, bzip2) and collection. The data itself is stored separately from the job in
the `rocketjob_slices` MongoDB client: `Sliced::Input` and `Sliced::Output` (both subclasses of
`Sliced::Slices`) manage dynamically created collections of `Sliced::Slice` documents, each holding a
batch of records for one worker to process.
## Runtime: Supervisor, Server, Workers
A running process is driven by the `Supervisor`, started via `bin/rocketjob` (`RocketJob::CLI`). It
registers a `Server` document, manages a `WorkerPool` of `Worker` threads (`ThreadWorker`), handles
OS signals, and runs the listeners. Cross-process coordination (shutdown, pause, log-level changes)
does not use a separate broker: it rides on MongoDB through [`RocketJob::Event`](events.html) and the
`Subscriber` / `Subscribers::*` classes.
## Class diagram
The core classes and their relationships. The diagram leaves out the smaller pieces (the remaining
`Plugins::Job::*` modules, the serializer-specific slice classes such as `EncryptedSlice` and
`BZip2OutputSlice`, the built-in jobs under `RocketJob::Jobs`, and `Subscribers::SecretConfig`) to
keep it legible. They follow the same patterns as the classes shown.
~~~mermaid
classDiagram
direction LR
%% ===== Persistence foundation =====
class MongoidDocument["Mongoid::Document"]
class Document["Plugins::Document"] {
<>
store_in client rocketjob
+find_and_update()
}
MongoidDocument <|.. Document : includes
%% ===== Public job interface =====
class Job["RocketJob::Job"] {
+perform()
+priority +description
+state (aasm)
+start! complete! fail! abort!
}
Document <|.. Job : includes
Job ..|> JobModel : includes
Job ..|> StateMachinePlugin : includes
Job ..|> JobWorker : includes
Job ..|> Throttle : includes
class JobModel["Plugins::Job::Model"]
class StateMachinePlugin["Plugins::StateMachine (aasm)"]
class JobWorker["Plugins::Job::Worker"]
class Throttle["Plugins::Job::Throttle"]
%% ===== Optional capability mixins =====
class Batch["RocketJob::Batch"] {
<>
+upload() +download()
input_category / output_category
}
class Cron["Plugins::Cron"]
class Singleton["Plugins::Singleton"]
class Retry["Plugins::Retry"]
Job <.. Batch : opt-in mixin
Job <.. Cron : opt-in mixin
Job <.. Singleton : opt-in mixin
Job <.. Retry : opt-in mixin
%% ===== Categories =====
class CategoryBase["Category::Base"] {
<>
+name +serializer +columns +format
}
class CategoryInput["Category::Input"]
class CategoryOutput["Category::Output"]
CategoryBase <|.. CategoryInput : includes
CategoryBase <|.. CategoryOutput : includes
Batch o--> "*" CategoryInput : input_categories
Batch o--> "*" CategoryOutput : output_categories
%% ===== Sliced storage (rocketjob_slices) =====
class Slices["Sliced::Slices"] {
+slice_size +collection_name
+upload download
}
class SlicedInput["Sliced::Input"]
class SlicedOutput["Sliced::Output"]
class Slice["Sliced::Slice"] {
Array of records + state
}
Slices <|-- SlicedInput
Slices <|-- SlicedOutput
Document <|.. Slice : includes
Slices o--> "*" Slice : holds
Batch ..> SlicedInput : input data
Batch ..> SlicedOutput : output data
%% ===== Runtime =====
class Supervisor {
+self.run
+supervise_pool
}
class Server {
+state (aasm)
+heartbeat
}
class WorkerPool {
+rebalance(max_workers)
}
class Worker {
+run +shutdown!
}
class ThreadWorker
Document <|.. Server : includes
Worker <|-- ThreadWorker
Supervisor o--> "1" Server : registers
Supervisor o--> "1" WorkerPool : manages
WorkerPool o--> "*" Worker : runs
Worker ..> Job : reserves & performs
%% ===== Coordination (pub/sub over MongoDB) =====
class Event["RocketJob::Event"]
class Subscriber["RocketJob::Subscriber"]
class SubServer["Subscribers::Server"]
class SubWorker["Subscribers::Worker"]
class SubLogger["Subscribers::Logger"]
Document <|.. Event : includes
Subscriber <|-- SubServer
Subscriber <|-- SubWorker
Subscriber <|-- SubLogger
Supervisor ..> Event : listens
Subscriber ..> Event : publishes/consumes
~~~
## Next steps
* [Programmer's Guide](guide.html): the core job API, including [Thread Safety](guide.html#thread-safety)
and [Extending Jobs with Plugins](guide.html#extending-jobs-with-plugins).
* [Batch Guide](batch.html): parallel processing across many workers.
* [How it works](index.html#how-it-works): a shorter overview on the landing page.
---
## Upgrading Rocket Job
Release notes for every version are published in the
[GitHub Releases](https://github.com/reidmorrison/rocketjob/releases). This page collects the
upgrade steps that need code or data changes when moving between major versions.
## Upgrading to v6
- Support for Ruby v3 and Rails 6.
- Major enhancements in Batch job support:
- Direct built-in Tabular support for all input and output categories.
- Multiple output file support, each with its own settings for:
- Compression: GZip, Zip, BZip2 (chunked for much faster loading into Apache Spark).
- Encryption: PGP, Symmetric Encryption.
- File format: CSV, PSV, JSON, Fixed Format, xlsx.
- Significant error handling improvements, especially around throttle failures that used to result
in "hanging" jobs.
- Removed use of Symbols to meet the Symbol deprecation in MongoDB and Mongoid.
### Deprecated Tabular plugins
The following plugins have been deprecated and are no longer loaded by default.
- `RocketJob::Batch::Tabular::Input`
- `RocketJob::Batch::Tabular::Output`
If your code relies on these plugins and you still want to upgrade to Rocket Job v6, add the
following require statement to any jobs that still use them:
~~~ruby
require "rocket_job/batch/tabular"
~~~
It is important to migrate away from these plugins, since they will be removed in a future release.
### Scheduled jobs
For any scheduled jobs that include the `RocketJob::Plugins::Cron` plugin, the default behavior has
changed so that the scheduled job instance is created immediately after the currently scheduled
instance starts.
To maintain the old behavior of creating the job when it fails, aborts, or completes, add the
following line to each of the applicable jobs:
~~~ruby
self.cron_after_start = false
~~~
Additionally, scheduled jobs now prevent a new one from being created when another scheduled
instance of the same job is already queued, or running with the _same_ `cron_schedule`.
To maintain the old behavior of allowing multiple instances with the same cron schedule, add the
following line to each of the applicable jobs:
~~~ruby
self.cron_singleton = false
~~~
Since scheduled jobs now implement their own singleton logic, remove the singleton plugin from any
scheduled jobs.
### Batch jobs
Rocket Job v6 replaces the array of symbols for `input_categories` and `output_categories` with an
array of `RocketJob::Category::Input` and `RocketJob::Category::Output`.
Jobs that added or modified the input or output categories need to be upgraded. For example:
~~~ruby
class MyJob < RocketJob::Job
include RocketJob::Batch
self.output_categories = [:main, :errors, :ignored]
end
~~~
Needs to be changed to:
~~~ruby
class MyJob < RocketJob::Job
include RocketJob::Batch
output_category name: :main
output_category name: :errors
output_category name: :ignored
end
~~~
#### slice_size, encrypt, compress
These fields have been removed from the job itself:
~~~ruby
class MyJob < RocketJob::Job
include RocketJob::Batch
self.slice_size = 1_000
self.encrypt = true
self.compress = true
end
~~~
They are now specified on the `input_category` as follows:
- `slice_size` just moves under `input_category`.
- `encrypt` becomes an option to `serializer`.
- `compress` is now the default for all batch jobs, so it is not needed.
If the serializer is set to `encrypt` then it is automatically compressed.
~~~ruby
class MyJob < RocketJob::Job
include RocketJob::Batch
input_category slice_size: 1_000, serializer: :encrypt
end
~~~
#### collect_output, collect_nil_output
The following fields have been moved from the job itself:
~~~ruby
class MyJob < RocketJob::Job
include RocketJob::Batch
self.collect_output = true
self.collect_nil_output = true
end
~~~
Into the corresponding `output_category`:
- `collect_output` no longer has any meaning. Output is collected anytime an `output_category` is
defined.
- `collect_nil_output` is now the option `nils` on the `output_category`. It defaults to `false` so
that by default any `nil` output from the `perform` method is not collected.
~~~ruby
class MyJob < RocketJob::Job
include RocketJob::Batch
output_category nils: true
end
~~~
#### Category name
For both `input_category` and `output_category`, when the `name` argument is not supplied it
defaults to `:main`. For example:
~~~ruby
class MyJob < RocketJob::Job
include RocketJob::Batch
input_category name: :main, serializer: :encrypt
output_category name: :main
end
~~~
Is the same as:
~~~ruby
class MyJob < RocketJob::Job
include RocketJob::Batch
input_category serializer: :encrypt
output_category
end
~~~
#### Existing and in-flight jobs
When migrating to Rocket Job v6, it is recommended to load every job and then save it back again as
part of the deployment. When the job loads it will automatically convert itself from the old schema
to the new v6 schema.
In-flight jobs should not be affected, other than it is important to shut down all running batch
servers _before_ running any new instances.
## Upgrading to v3
V3 replaces MongoMapper with Mongoid, which supports the latest MongoDB Ruby client driver.
### Mongo config file
Replace `mongo.yml` with `mongoid.yml`. Start with the sample
[mongoid.yml](https://github.com/reidmorrison/rocketjob/blob/main/test/config/mongoid.yml).
Note: the `rocketjob` and `rocketjob_slices` clients in the above `mongoid.yml` file are both
required.
### Other changes
Arguments are no longer supported. Use fields for defining all named arguments for a job.
Replace usages of `rocket_job do` to set default values:
~~~ruby
rocket_job do |job|
job.priority = 25
end
~~~
With:
~~~ruby
self.priority = 25
~~~
Replace `key` with `field` when adding attributes to a job:
~~~ruby
key :inquiry_defaults, Hash
~~~
With:
~~~ruby
field :inquiry_defaults, type: Hash, default: {}
~~~
Replace usage of `public_rocket_job_properties` with the `user_editable` option:
~~~ruby
field :priority, type: Integer, default: 50, user_editable: true
~~~